discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
xorbitsai/inference · source
Snapshot 0 · 2026-11-04T12:47:27Z · Python · Apache-2.0
Content fingerprint
da51a024230ee3a8ed242053a60088238435598e148a4049498de33db2f8e28bGitHub description at capture
Swap GPT for any LLM by changing a single line of code. Xinference lets you run open-source, speech, and multimodal models on cloud, on-prem, or your laptop — all through one unified, production-ready inference API.
README at capture
<div align="center">
<img src="./assets/xorbits-logo.png" width="180px" alt="xorbits" />
# Xorbits Inference: Model Serving Made Easy 🤖
<p align="center">
<a href="https://xinference.co">Xinference Enterprise</a> ·
<a href="https://inference.readthedocs.io/en/latest/getting_started/installation.html#installation">Self-hosting</a> ·
<a href="https://inference.readthedocs.io/">Documentation</a>
</p>
[](https://pypi.org/project/xinference/)
[](https://github.com/xorbitsai/inference/blob/main/LICENSE)
[](https://actions-badge.atrox.dev/xorbitsai/inference/goto?ref=main)
[](https://hub.docker.com/r/xprobe/xinference)
[](https://discord.gg/Xw9tszSkr5)
[](https://t.me/+nCNpwmySwk9iYmI1)
[](https://twitter.com/xorbitsio)
<p align="center">
<a href="./README.md"><img alt="English" src="https://img.shields.io/badge/English-454545?style=for-the-badge"></a>
<a href="./READMES/README_ja_JP.md"><img alt="日本語" src="https://img.shields.io/badge/日本語-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_ko.md"><img alt="한국어" src="https://img.shields.io/badge/한국어-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_de.md"><img alt="Deutsch" src="https://img.shields.io/badge/Deutsch-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_fr.md"><img alt="Français" src="https://img.shields.io/badge/Français-d9d9d9?style=for-the-badge"></a>
<br>
<a href="./READMES/README_es.md"><img alt="Español" src="https://img.shields.io/badge/Español-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_it.md"><img alt="Italiano" src="https://img.shields.io/badge/Italiano-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_pt_BR.md"><img alt="Português" src="https://img.shields.io/badge/Português-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_zh_TW.md"><img alt="繁體中文" src="https://img.shields.io/badge/繁體中文-d9d9d9?style=for-the-badge"></a>
<a href="./READMES/README_zh_CN.md"><img alt="简体中文" src="https://img.shields.io/badge/简体中文-d9d9d9?style=for-the-badge"></a>
</p>
</div>
<br />
Xorbits Inference(Xinference) is a powerful and versatile library designed to serve language,
speech recognition, and multimodal models. With Xorbits Inference, you can effortlessly deploy
and serve your or state-of-the-art built-in models using just a single command. Whether you are a
researcher, developer, or data scientist, Xorbits Inference empowers you to unleash the full
potential of cutting-edge AI models.
<div align="center">
<i><a href="https://discord.gg/Xw9tszSkr5">👉 Join our Discord community!</a> · <a href="https://t.me/+nCNpwmySwk9iYmI1">Join our Telegram group!</a></i>
</div>
## 🔥 Hot Topics
### Framework Enhancements
- Xinference 4.0.0 is available with multi-engine Xavier, heterogeneous P/D, and runtime model reconfiguration: [Release Notes](https://github.com/xorbitsai/inference/releases/tag/v4.0.0)
- Agent-native Serving: Xinference integrates with [Xagent](https://github.com/xorbitsai/xagent) to enable dynamic planning, tool use, and autonomous multi-step reasoning — moving beyond static pipelines.
- Auto batch: Multiple concurrent requests are automatically batched, significantly improving throughput: [#4197](https://github.com/xorbitsai/inference/pull/4197)
- [Xllamacpp](https://github.com/xorbitsai/xllamacpp): New llama.cpp Python binding, maintained by Xinference team, supports continuous batching and is more production-ready.: [#2997](https://github.com/xorbitsai/inference/pull/2997)
- Distributed inference: running models across workers: [#2877](https://github.com/xorbitsai/inference/pull/2877)
- VLLM enhancement: Shared KV cache across multiple replicas: [#2732](https://github.com/xorbitsai/inference/pull/2732)
### New Models
- Built-in support for [FLUX 3 Image Klein](https://huggingface.co/black-forest-labs/flux-3-image-klein): [#5792](https://github.com/xorbitsai/inference/pull/5792)
- Built-in support for FIBO 2.0 series ([Dev](https://huggingface.co/briaai/Fibo-2.0-dev), [Edit Turbo](https://huggingface.co/briaai/Fibo-2.0-edit-turbo)): [#5790](https://github.com/xorbitsai/inference/pull/5790)
- Built-in support for Ming-3.0 TTS series ([Tiny](https://huggingface.co/inclusionAI/Ming-3.0-tts-tiny), [0.5B](https://huggingface.co/inclusionAI/Ming-3.0-tts-0.5B)): [#5788](https://github.com/xorbitsai/inference/pull/5788)
- Built-in support for [Xiaomi-OCR-0](https://huggingface.co/SeerRay-Lab/Xiaomi-OCR-0): [#5764](https://github.com/xorbitsai/inference/pull/5764)
- Built-in support for [MOSS-Image-SFT](https://huggingface.co/OpenMOSS-Team/MOSS-Image-SFT): [#5755](https://github.com/xorbitsai/inference/pull/5755)
- Built-in support for [DeepSeek-V4.1-Flash-1017](https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017): [#5753](https://github.com/xorbitsai/inference/pull/5753)
- Built-in support for Iris-3B series ([Base](https://huggingface.co/speridlabs/iris-3b), [Turbo](https://huggingface.co/speridlabs/iris-3b/tree/main/turbo)): [#5686](https://github.com/xorbitsai/inference/pull/5686)
- Built-in support for MiniCPM-V-4.7 series ([1B](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B), [35B-A3B](https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B)): [#5676](https://github.com/xorbitsai/inference/pull/5676)
- Built-in support for Qwen3.8-Flash-Next series ([Base](https://huggingface.co/Qwen/Qwen3.8-Flash-Next), [FP8](https://huggingface.co/Qwen/Qwen3.8-Flash-Next-FP8)): [#5673](https://github.com/xorbitsai/inference/pull/5673)
- Built-in support for GLM-5.3 series ([BF16](https://huggingface.co/zai-org/GLM-5.3-BF16), [FP8](https://huggingface.co/zai-org/GLM-5.3)): [#5666](https://github.com/xorbitsai/inference/pull/5666)
- Built-in support for [Qwen-Image-2.1-Turbo](https://huggingface.co/Qwen/Qwen-Image-2.1-Turbo): [#5665](https://github.com/xorbitsai/inference/pull/5665)
- Built-in support for [DeepSeek-V4.1-Flash](https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash): [#5661](https://github.com/xorbitsai/inference/pull/5661)
- Built-in support for [EmbeddingGemma 2](https://huggingface.co/google/embeddinggemma-2): [#5644](https://github.com/xorbitsai/inference/pull/5644)
- Built-in support for [Confucius4-TTS](https://huggingface.co/netease-youdao/Confucius4-TTS): [#5591](https://github.com/xorbitsai/inference/pull/5591)
- Built-in support for [jina-ocr-v1](https://huggingface.co/jinaai/jina-ocr-v1): [#5588](https://github.com/xorbitsai/inference/pull/5588)
### Integrations
- [Xagent](https://github.com/xorbitsai/xagent): an enterprise agent platform for building and running AI agents with planning, memory, and tool use — not limited to rigid workflows.
- [Dify](https://marketplace.dify.ai/plugin/langgenius/xinference): an LLMOps platform that enables developers (and even non-developers) to quickly build useful applications based on large language models, ensuring they are visual, operable, and improvable.
- [FastGPT](https://github.com/labring/FastGPT): a knowledge-based platform built on the LLM, offers out-of-the-box data processing and model invocation capabilities, allows for workflow orchestration through Flow visualization.
- [RAGFlow](https://github.com/infiniflow/ragflow): is an open-source RAG engine based on deep document understanding.
- [MaxKB](https://github.com/1Panel-dev/MaxKB): MaxKB = Max Knowledge Brain, it is a powerful and easy-to-use AI assistant that integrates Retrieval-Augmented Generation (RAG) pipelines, supports robust workflows, and provides advanced MCP tool-use capabilities.
## Key Features
🌟 **Model Serving Made Easy**: Simplify the process of serving large language, speech
recognition, and multimodal models. You can set up and deploy your models
for experimentation and production with a single command.
⚡️ **State-of-the-Art Models**: Experiment with cutting-edge built-in models using a single
command. Inference provides access to state-of-the-art open-source models!
🖥 **Heterogeneous Hardware Utilization**: Make the most of your hardware resources with
[ggml](https://github.com/ggerganov/ggml). Xorbits Inference intelligently utilizes heterogeneous
hardware, including GPUs and CPUs, to accelerate your model inference tasks.
⚙️ **Flexible API and Interfaces**: Offer multiple interfaces for interacting
with your models, supporting OpenAI compatible RESTful API (including Function Calling API), RPC, CLI
and WebUI for seamless model management and interaction.
🌐 **Distributed Deployment**: Excel in distributed deployment scenarios,
allowing the seamless distribution of model inference across multiple devices or machines.
🔌 **Built-in Integration with Third-Party Libraries**: Xorbits Inference seamlessly integrates
with popular third-party libraries including [LangChain](https://reference.langchain.com/python/langchain-community/llms/xinference/Xinference), [LlamaIndex](https://developers.llamaindex.ai/python/framework/integrations/llm/xinference_local_deployment/), [Dify](https://marketplace.dify.ai/plugin/langgenius/xinference), and [Chatbox](https://chatboxai.app/).
## Why Xinference
| Feature | Xinference | FastChat | OpenLLM | RayLLM |
|------------------------------------------------|------------|----------|---------|--------|
| OpenAI-Compatible RESTful API | ✅ | ✅ | ✅ | ✅ |
| vLLM Integrations | ✅ | ✅ | ✅ | ✅ |
| More Inference Engines (GGML, TensorRT) | ✅ | ❌ | ✅ | ✅ |
| More Platforms (CPU, Metal) | ✅ | ✅ | ❌ | ❌ |
| Multi-node Cluster Deployment | ✅ | ❌ | ❌ | ✅ |
| Image Models (Text-to-Image) | ✅ | ✅ | ❌ | ❌ |
| Text Embedding Models | ✅ | ❌ | ❌ | ❌ |
| Multimodal Models | ✅ | ❌ | ❌ | ❌ |
| Audio Models | ✅ | ❌ | ❌ | ❌ |
| More OpenAI Functionalities (Function Calling) | ✅ | ❌ | ❌ | ❌ |
## Using Xinference
- **Self-hosting Xinference Community Edition</br>**
Quickly get Xinference running in your environment with this [starter guide](#getting-started).
Use our [documentation](https://inference.readthedocs.io/) for further references and more in-depth instructions.
- **Xinference for enterprise / organizations</br>**
**Xinference Enterprise** is the commercial edition for teams running models in production. Deploy it in your own cloud or data centre, or choose a managed dedicated deployment with **Xinference Cloud**. The hosted **Model API** gives you access to supported models through an OpenAI-compatible API without managing inference infrastructure. Learn more at [xinference.co](https://xinference.co).
For enterprise enquiries, [email us](mailto:info@xinference.co?subject=[GitHub]Business%20License%20Inquiry).
## Staying Ahead
Star Xinference on GitHub and be instantly notified of new releases.

## Getting Started
* [Docs](https://inference.readthedocs.io/en/latest/index.html)
* [Built-in Models](https://inference.readthedocs.io/en/latest/models/builtin/index.html)
* [Custom Models](https://inference.readthedocs.io/en/latest/models/custom.html)
* [Deployment Docs](https://inference.readthedocs.io/en/latest/getting_started/using_xinference.html)
### Quick Start
**pip**
```bash
pip install xinference
xinference-local
```
**One-command installer**
Linux/macOS:
```bash
curl -fsSL https://raw.githubusercontent.com/xorbitsai/inference/main/scripts/install.sh | sh
```
Windows PowerShell:
```powershell
irm https://raw.githubusercontent.com/xorbitsai/inference/main/scripts/install.ps1 | iex
```
[Installation guide](https://inference.readthedocs.io/en/latest/getting_started/installation.html#one-line-install) · [Usage guide](https://inference.readthedocs.io/en/latest/getting_started/using_xinference.html#run-xinference-locally)
### Docker
Nvidia GPU users can start Xinference server using [Xinference Docker Image](https://inference.readthedocs.io/en/latest/getting_started/using_docker_image.html). Prior to executing the installation command, ensure that both [Docker](https://docs.docker.com/get-docker/) and [CUDA](https://developer.nvidia.com/cuda-downloads) are set up on your system.
```bash
docker run --name xinference -d -p 9997:9997 -e XINFERENCE_HOME=/data -v </on/your/host>:/data --gpus all xprobe/xinference:latest xinference-local -H 0.0.0.0
```
### K8s via helm
Ensure that you have GPU support in your Kubernetes cluster, then install as follows.
```
# add repo
helm repo add xinference https://xorbitsai.github.io/xinference-helm-charts
# update indexes and query xinference versions
helm repo update xinference
helm search repo xinference/xinference --devel --versions
# install xinference
helm install xinference xinference/xinference -n xinference --version 0.0.1-v<xinference_release_version>
```
For more customized installation methods on K8s, please refer to the [documentation](https://inference.readthedocs.io/en/latest/getting_started/using_kubernetes.html).

## Getting involved
| Platform | Purpose |
|-------------------------------------------------------------------------------------------------|---------------------------------------------|
| [Github Issues](https://github.com/xorbitsai/inference/issues) | Reporting bugs and filing feature requests. |
| [Discord](https://discord.gg/Xw9tszSkr5) | Collaborating with other Xinference users. |
| [Telegram](https://t.me/+nCNpwmySwk9iYmI1) | Chatting with other Xinference users. |
| [Twitter](https://twitter.com/xorbitsio) | Staying up-to-date on new features. |
## Citation
If this work is helpful, please kindly cite as:
```bibtex
@inproceedings{lu2024xinference,
title = "Xinference: Making Large Model Serving Easy",
author = "Lu, Weizheng and Xiong, Lingfeng and Zhang, Feng and Qin, Xuye and Chen, Yueguo",
booktitle = "Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
month = nov,
year = "2024",
address = "Miami, Florida, USA",
publisher = "Association for Computational Linguistics",
url = "https://aclanthology.org/2024.emnlp-demo.30",
pages = "291--300",
}
```
## Contributors
<a href="https://github.com/xorbitsai/inference/graphs/contributors">
<img src="https://contrib.rocks/image?repo=xorbitsai/inference" />
</a>
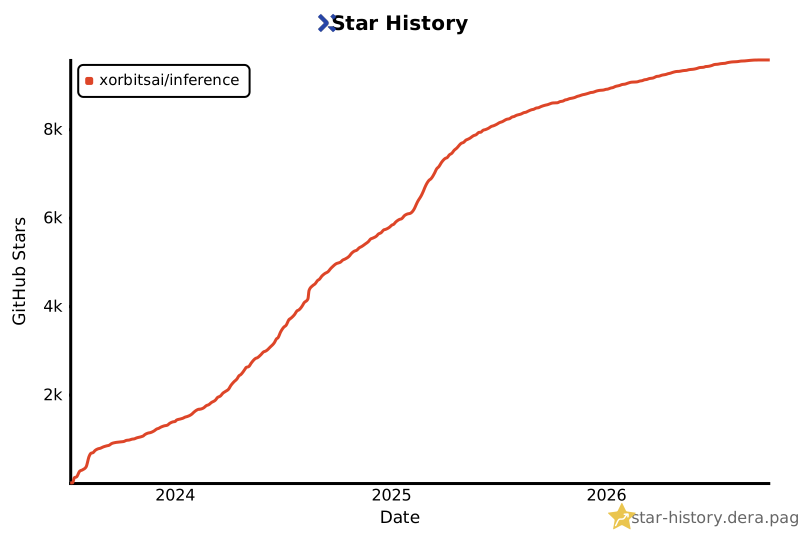
## Star History
[](https://star-history.dera.page/#xorbitsai/inference&Date)