discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
crawlab-team/crawlab · source
Snapshot 0 · 2026-11-04T12:47:25Z · Go · BSD-3-Clause
Content fingerprint
462b230b65df81e994f103be1c9103d78fe2575cbbf8541697b915dedf7171a1GitHub description at capture
Distributed web crawler admin platform for spiders management regardless of languages and frameworks. 分布式爬虫管理平台,支持任何语言和框架
README at capture
# Crawlab
<p>
<a href="https://github.com/crawlab-team/crawlab/actions/workflows/docker-crawlab.yml" target="_blank">
<img src="https://github.com/crawlab-team/crawlab/workflows/Docker%20Image%20CI:%20crawlab/badge.svg">
</a>
<a href="https://github.com/crawlab-team/crawlab/releases" target="_blank">
<img src="https://img.shields.io/github/release/crawlab-team/crawlab.svg?logo=github">
</a>
<a href="https://github.com/crawlab-team/crawlab/commits/main" target="_blank">
<img src="https://img.shields.io/github/last-commit/crawlab-team/crawlab.svg">
</a>
<a href="https://github.com/crawlab-team/crawlab/issues?q=is%3Aissue+is%3Aopen+label%3Abug" target="_blank">
<img src="https://img.shields.io/github/issues/crawlab-team/crawlab/bug.svg?label=bugs&color=red">
</a>
<a href="https://github.com/crawlab-team/crawlab/issues?q=is%3Aissue+is%3Aopen+label%3Aenhancement" target="_blank">
<img src="https://img.shields.io/github/issues/crawlab-team/crawlab/enhancement.svg?label=enhancements&color=cyan">
</a>
<a href="https://github.com/crawlab-team/crawlab/blob/main/LICENSE" target="_blank">
<img src="https://img.shields.io/github/license/crawlab-team/crawlab.svg">
</a>
</p>
[中文](https://github.com/crawlab-team/crawlab/blob/main/README-zh.md) | English
[Installation](#installation) | [Run](#run) | [Screenshot](#screenshot) | [Architecture](#architecture) | [Integration](#integration-with-other-frameworks) | [Compare](#comparison-with-other-frameworks) | [Community & Sponsorship](#community--sponsorship) | [CHANGELOG](https://github.com/crawlab-team/crawlab/blob/main/CHANGELOG.md) | [Disclaimer](https://github.com/crawlab-team/crawlab/blob/main/DISCLAIMER.md)
Golang-based distributed web crawler management platform, supporting various languages including Python, NodeJS, Go, Java, PHP and various web crawler frameworks including Scrapy, Puppeteer, Selenium.
[Demo](https://demo.crawlab.cn) | [Documentation](https://docs.crawlab.cn/en/)
## Installation
You can follow the [installation guide](https://docs.crawlab.cn/en/guide/installation/).
## Quick Start
Please open the command line prompt and execute the command below. Make sure you have installed `docker-compose` in advance.
```bash
git clone https://github.com/crawlab-team/examples
cd examples/docker/basic
docker-compose up -d
```
Next, you can look into the `docker-compose.yml` (with detailed config params) and the [Documentation](http://docs.crawlab.cn/en/) for further information.
## Run
### Docker
Please use `docker-compose` to one-click to start up. By doing so, you don't even have to configure MongoDB database. Create a file named `docker-compose.yml` and input the code below.
```yaml
version: '3.3'
services:
master:
image: crawlabteam/crawlab:latest
container_name: crawlab_example_master
environment:
CRAWLAB_NODE_MASTER: "Y"
CRAWLAB_MONGO_HOST: "mongo"
volumes:
- "./.crawlab/master:/root/.crawlab"
ports:
- "8080:8080"
depends_on:
- mongo
worker01:
image: crawlabteam/crawlab:latest
container_name: crawlab_example_worker01
environment:
CRAWLAB_NODE_MASTER: "N"
CRAWLAB_GRPC_ADDRESS: "master"
CRAWLAB_FS_FILER_URL: "http://master:8080/api/filer"
volumes:
- "./.crawlab/worker01:/root/.crawlab"
depends_on:
- master
worker02:
image: crawlabteam/crawlab:latest
container_name: crawlab_example_worker02
environment:
CRAWLAB_NODE_MASTER: "N"
CRAWLAB_GRPC_ADDRESS: "master"
CRAWLAB_FS_FILER_URL: "http://master:8080/api/filer"
volumes:
- "./.crawlab/worker02:/root/.crawlab"
depends_on:
- master
mongo:
image: mongo:4.2
container_name: crawlab_example_mongo
restart: always
```
Then execute the command below, and Crawlab Master and Worker Nodes + MongoDB will start up. Open the browser and enter `http://localhost:8080` to see the UI interface.
```bash
docker-compose up -d
```
For Docker Deployment details, please refer to [relevant documentation](https://docs.crawlab.cn/en/guide/installation/docker.html).
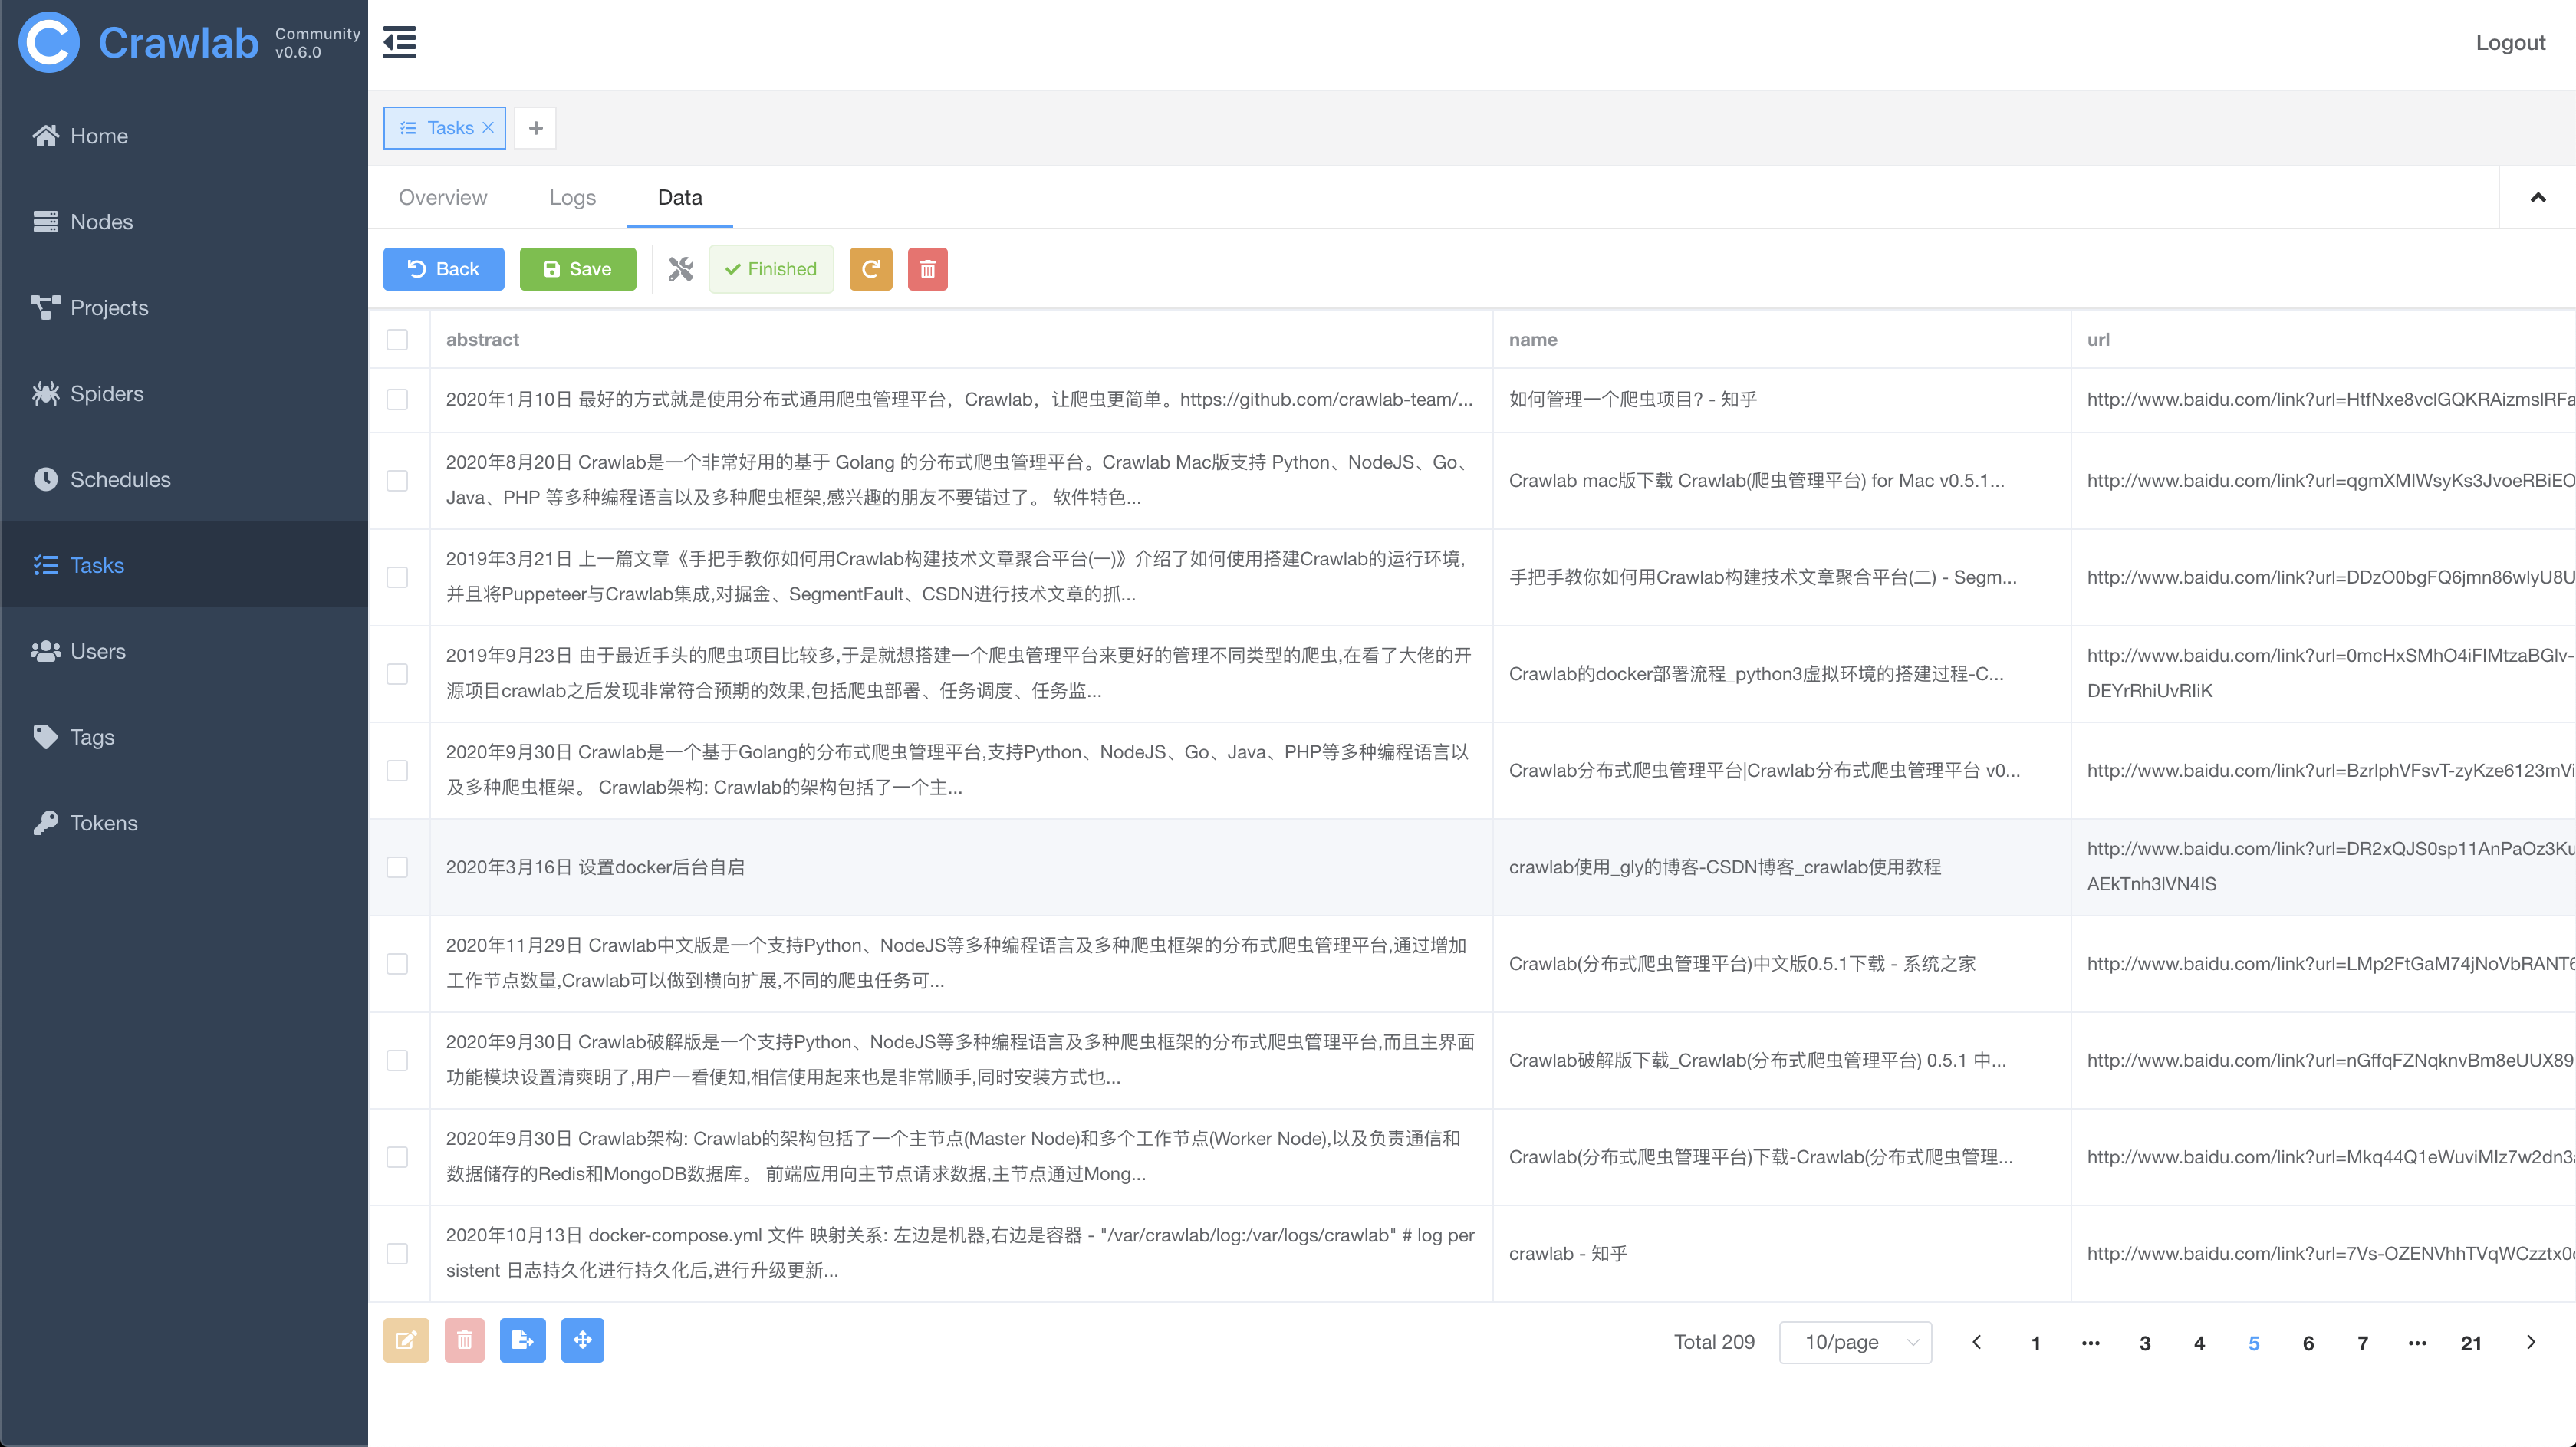
## Screenshot
#### Login

#### Home Page
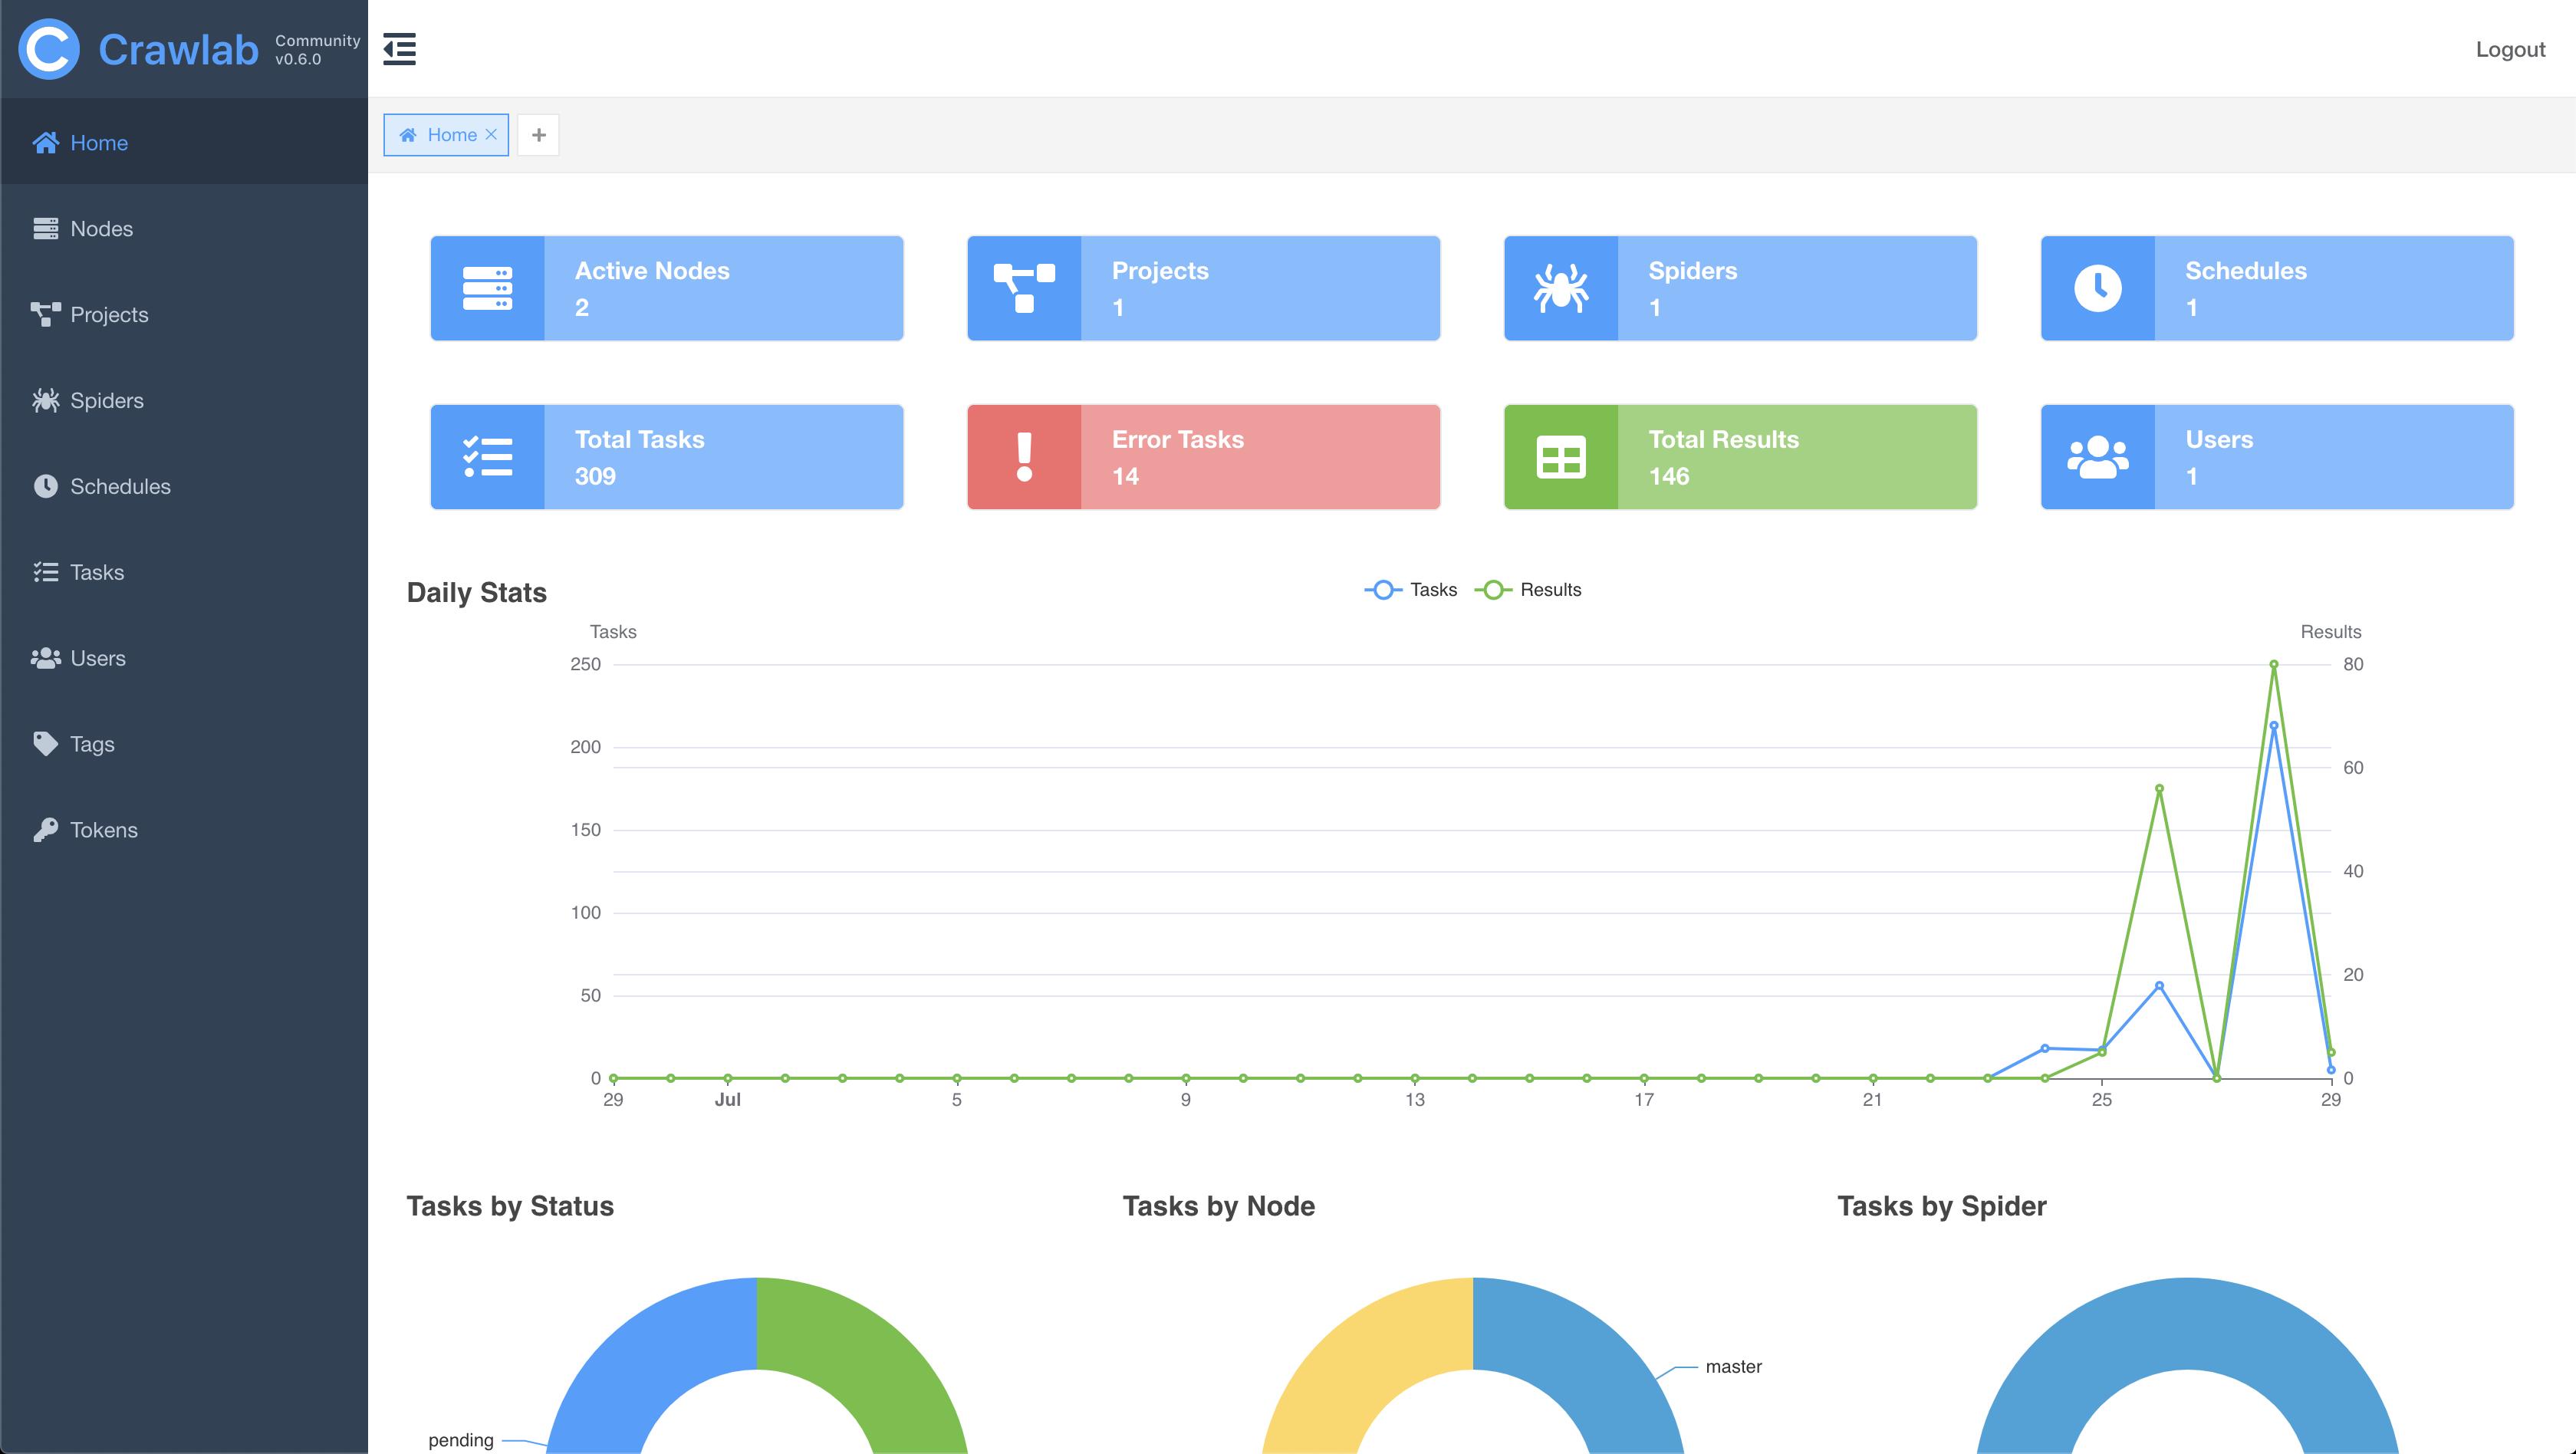
#### Node List
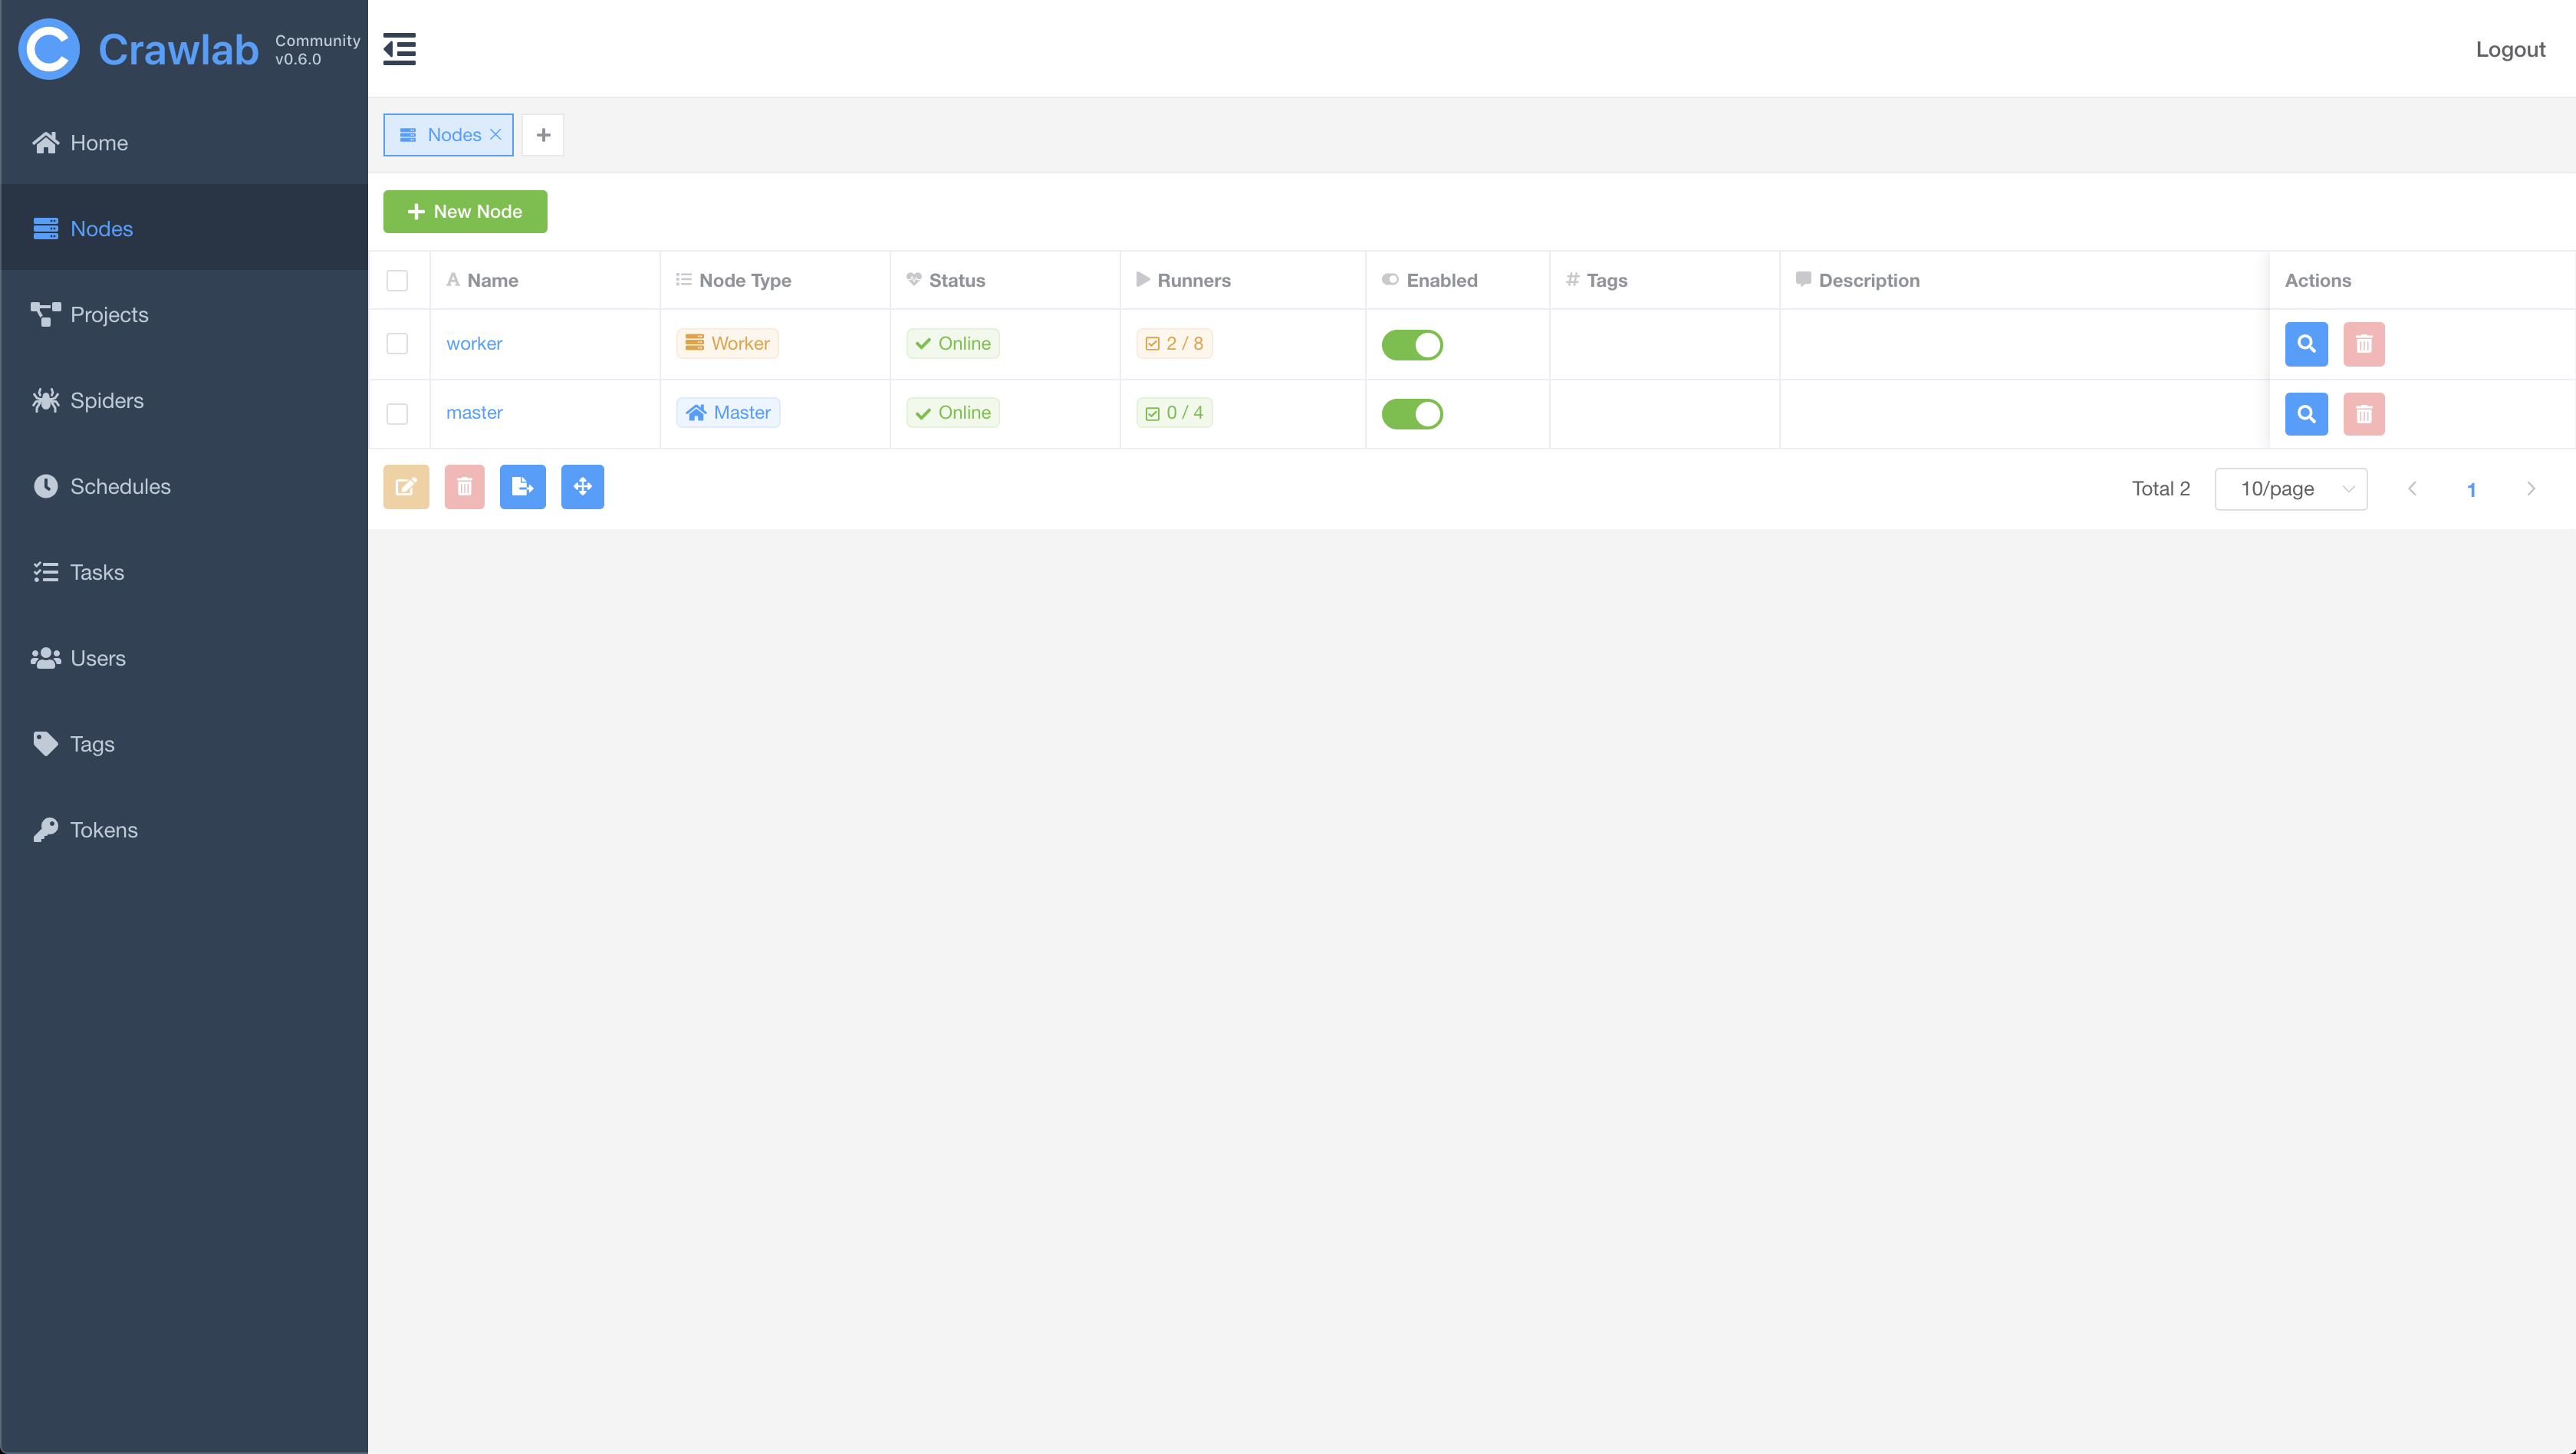
#### Spider List

#### Spider Overview

#### Spider Files
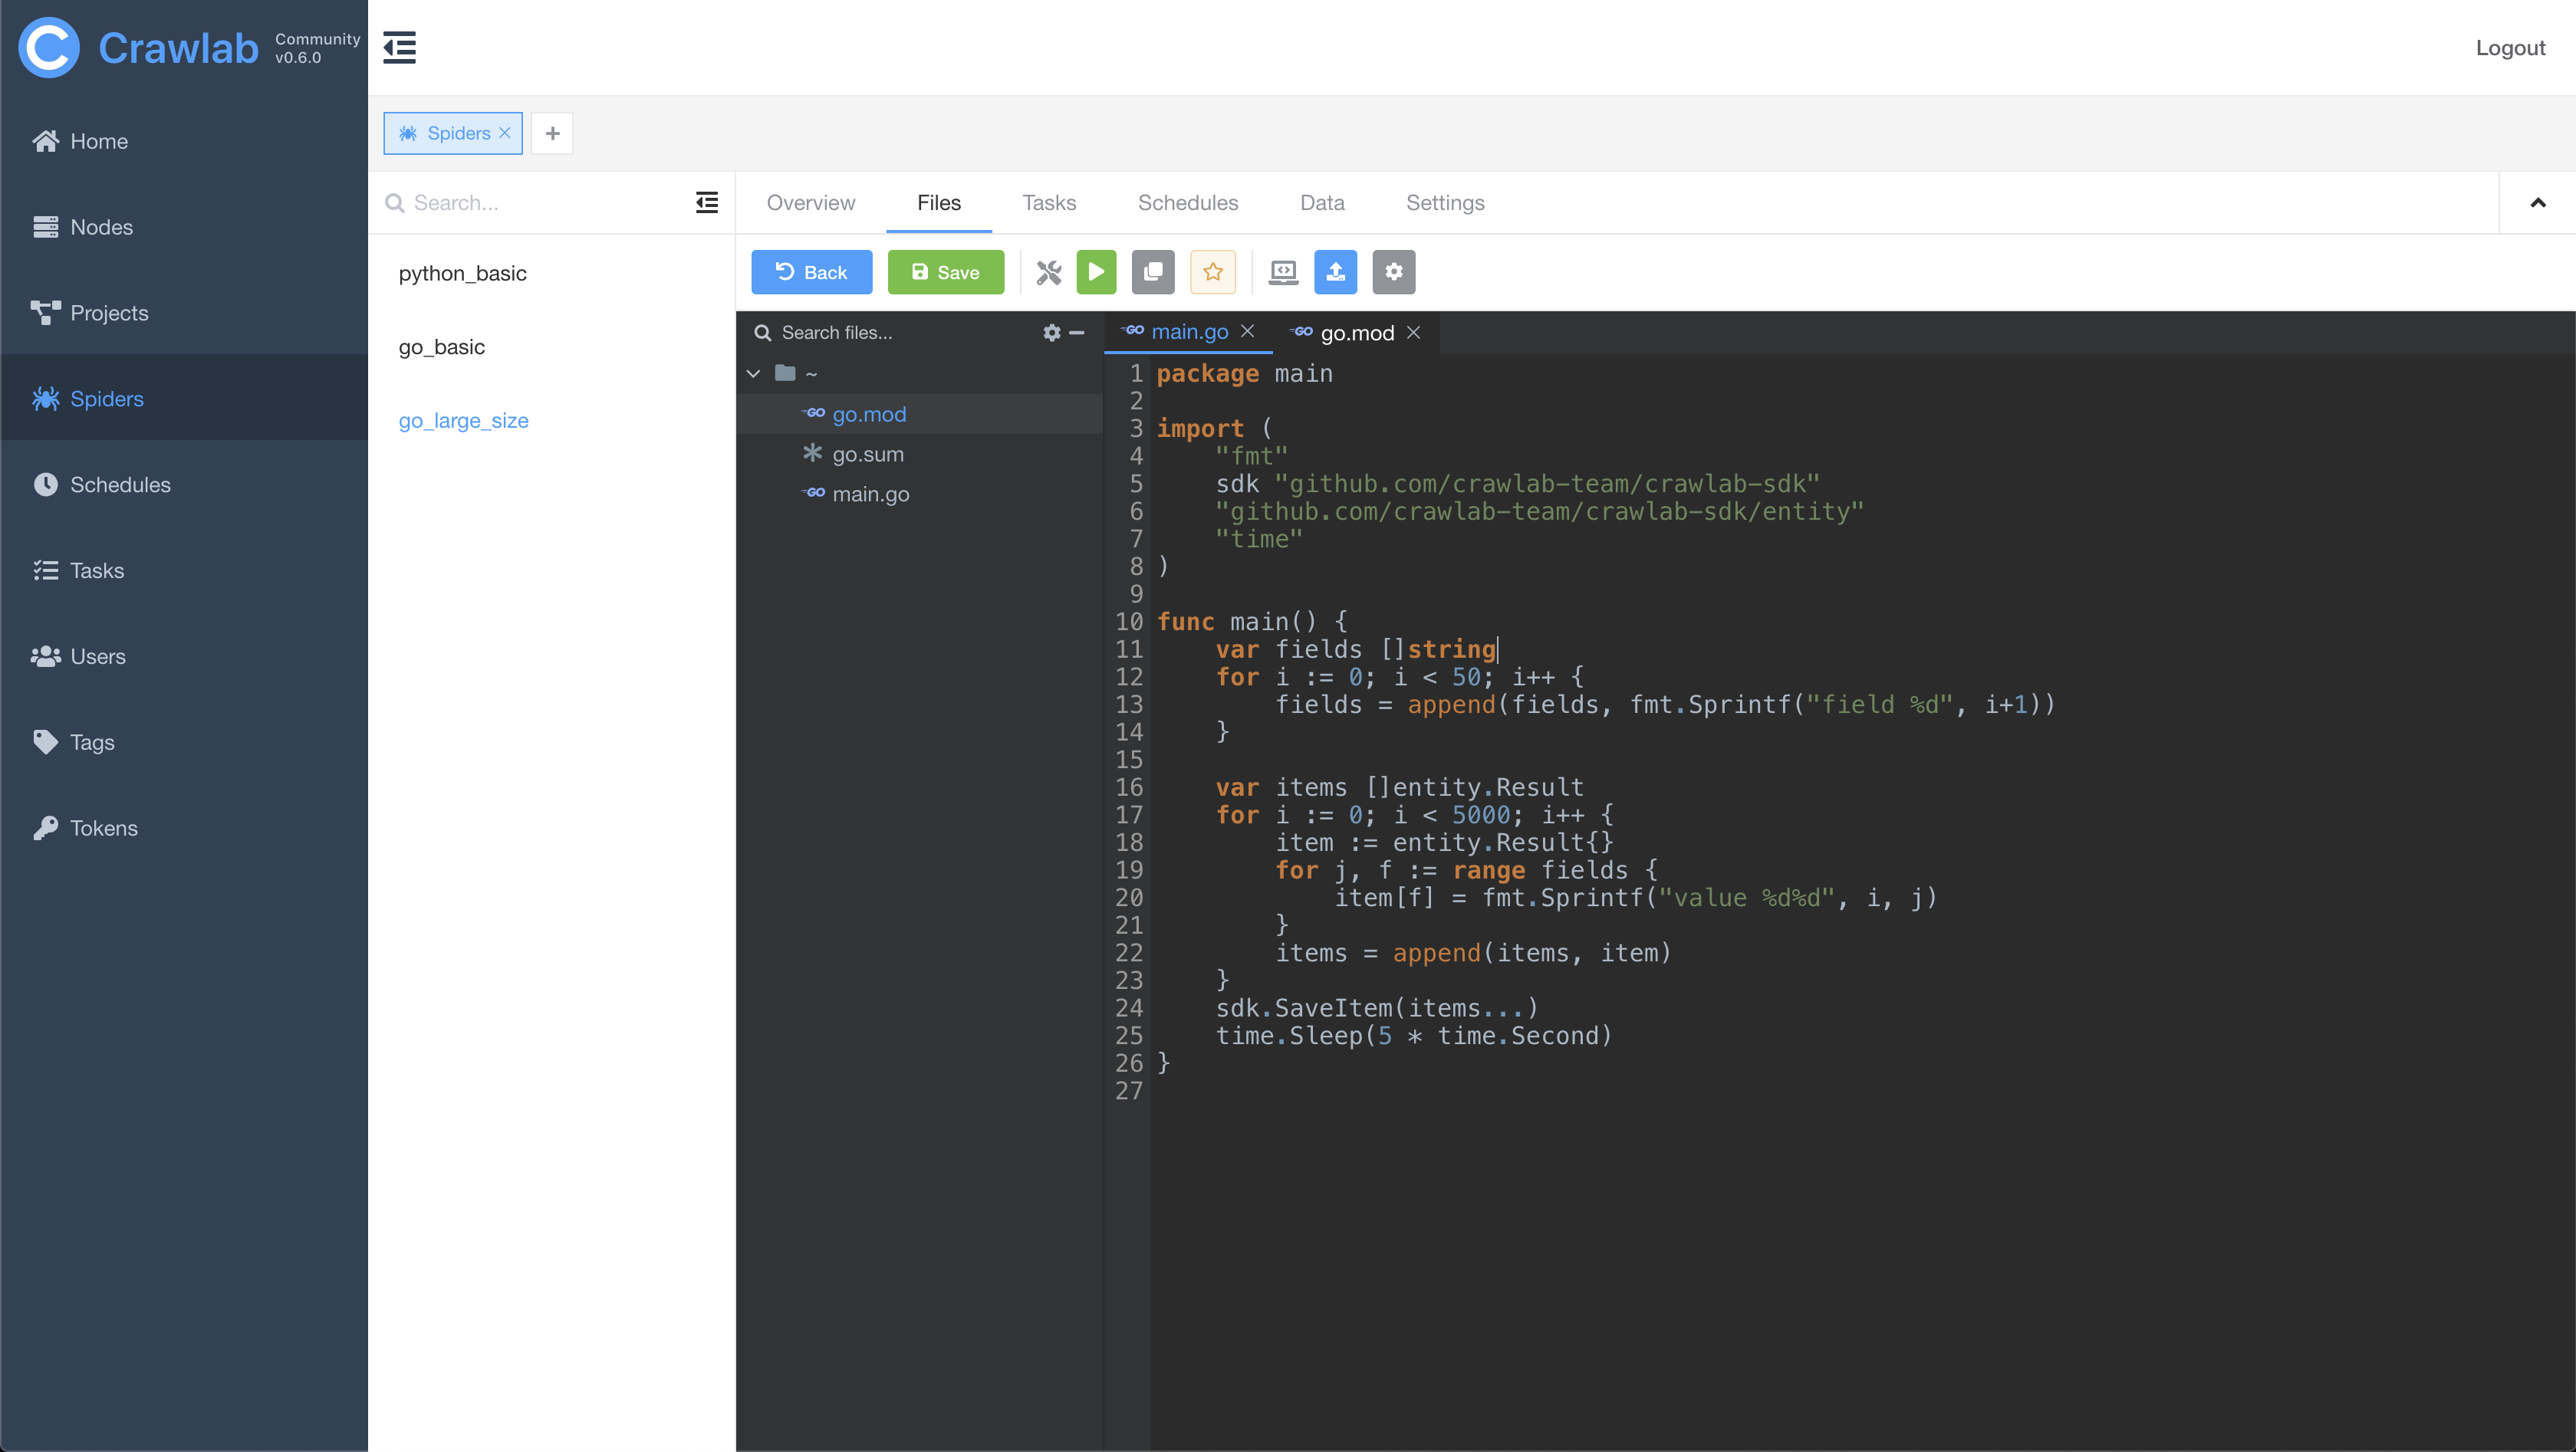
#### Task Log
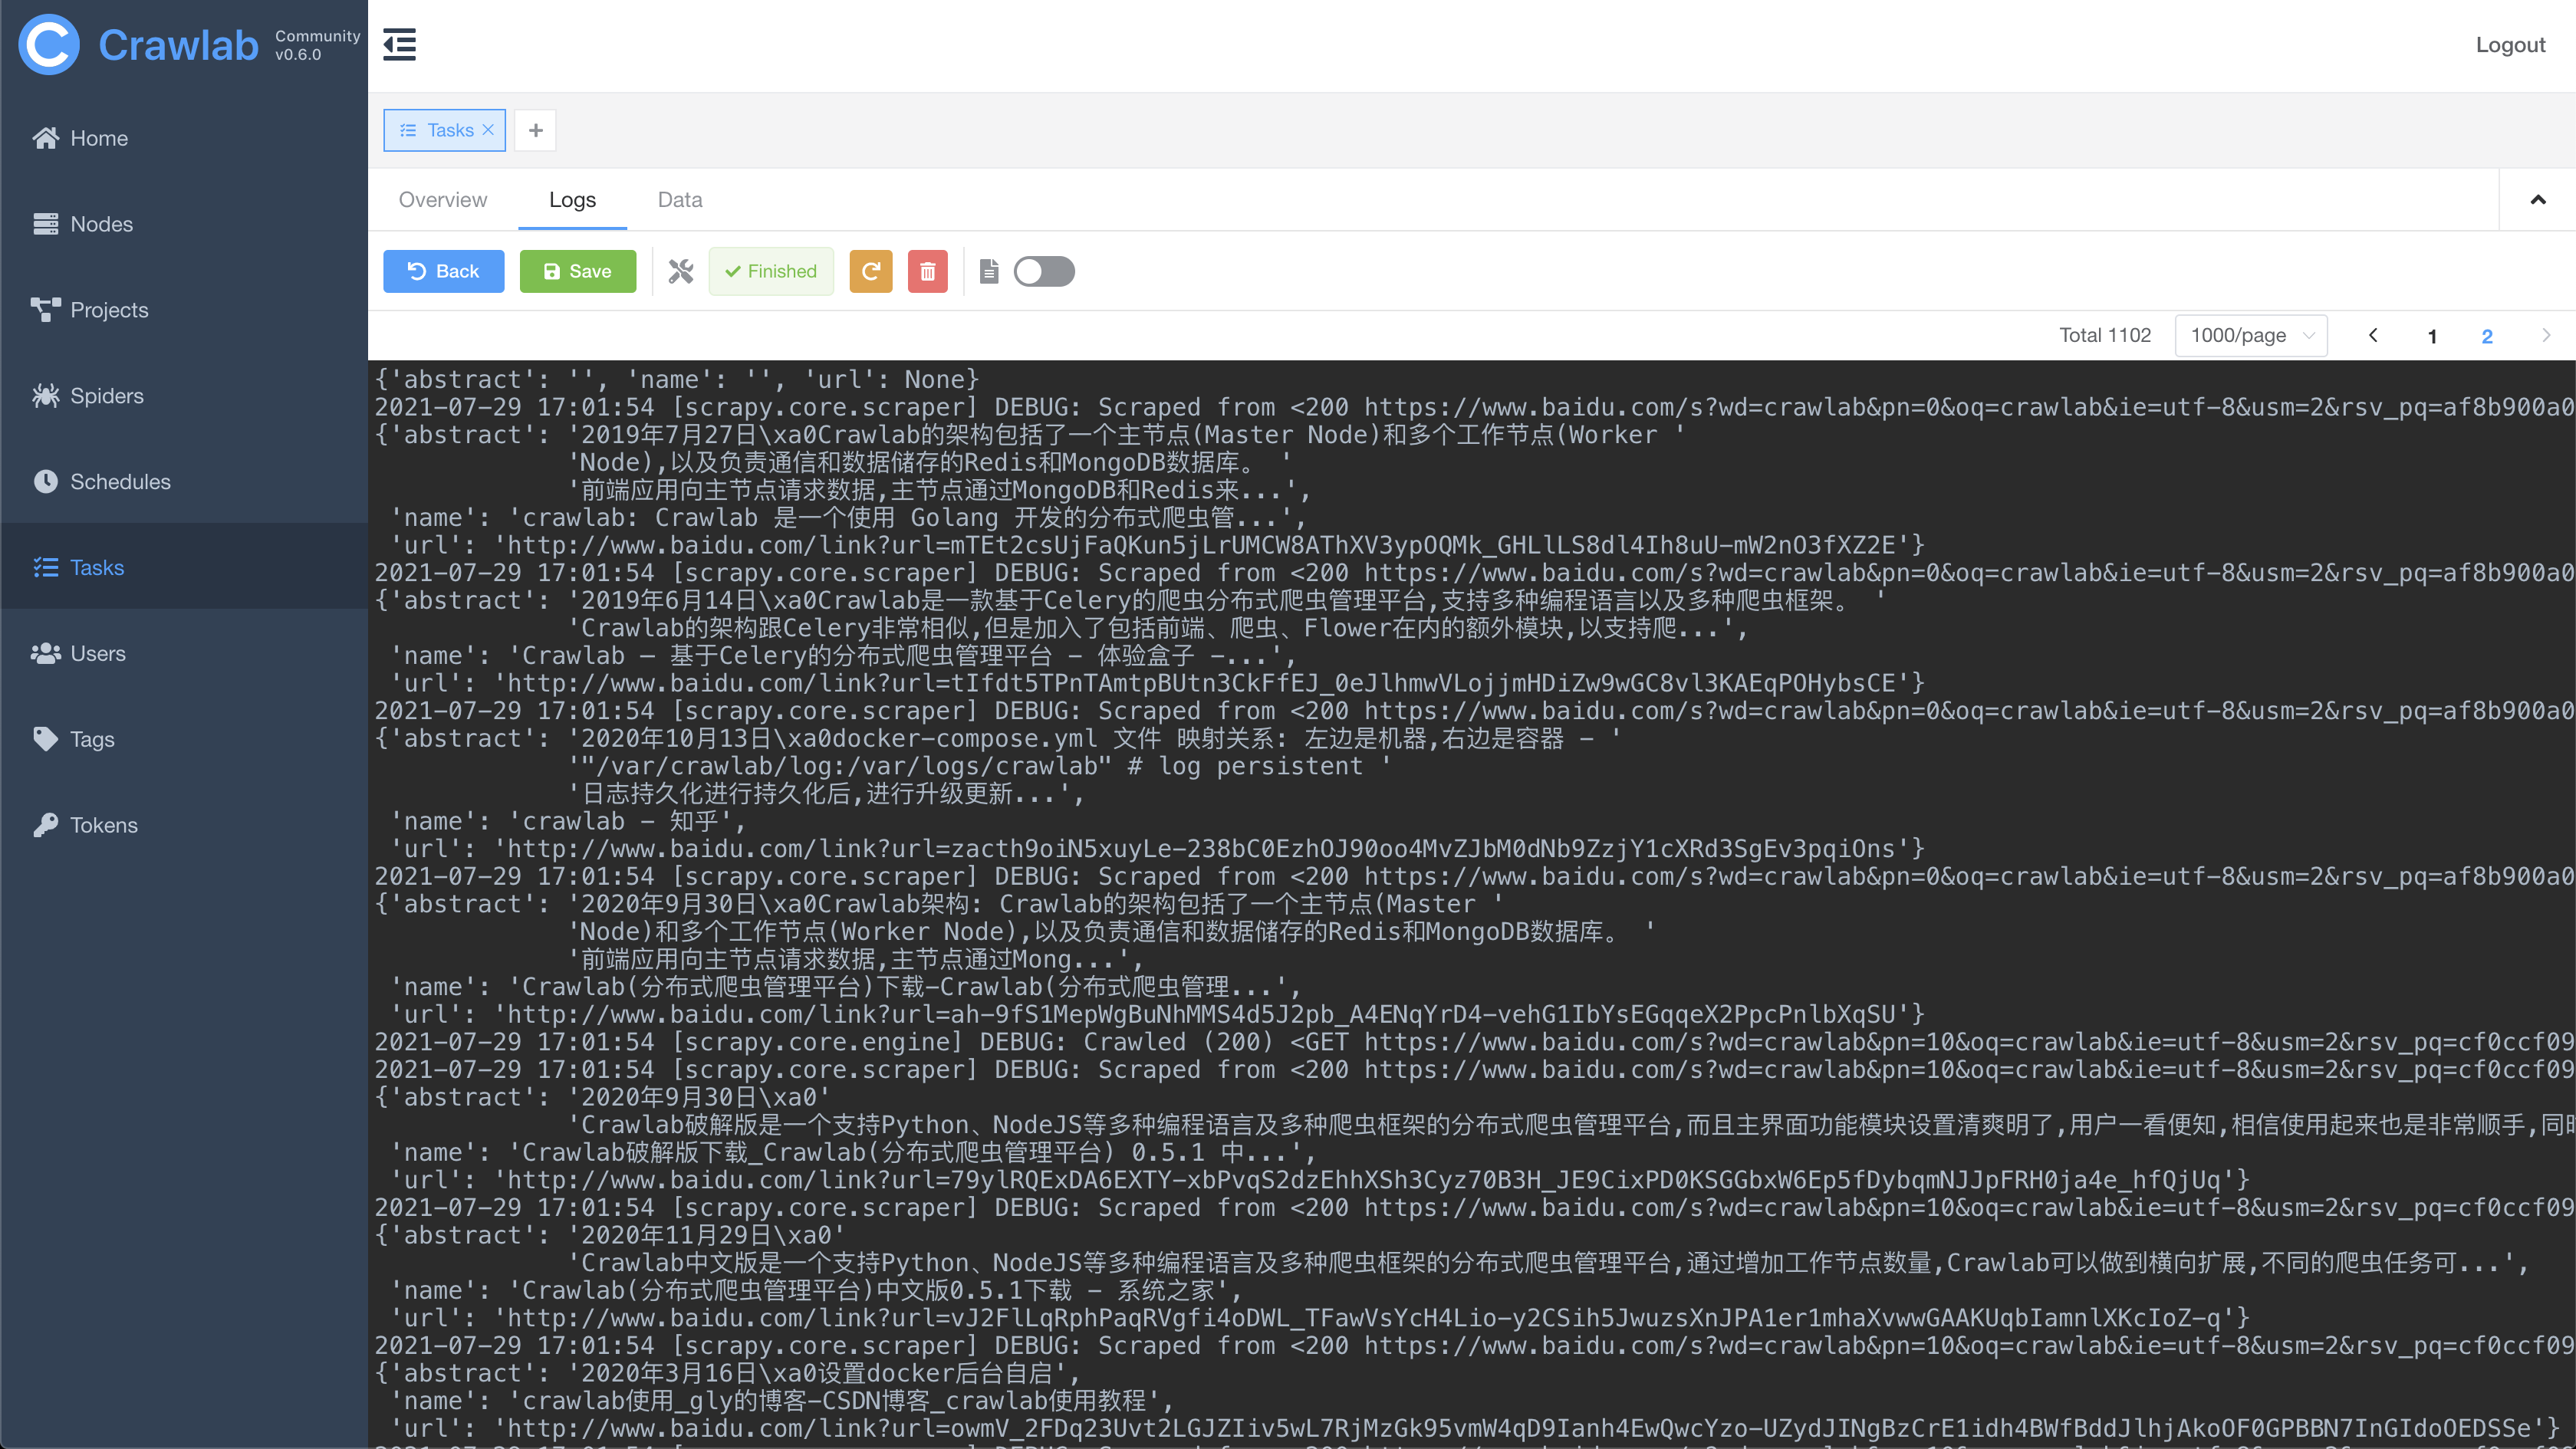
#### Task Results
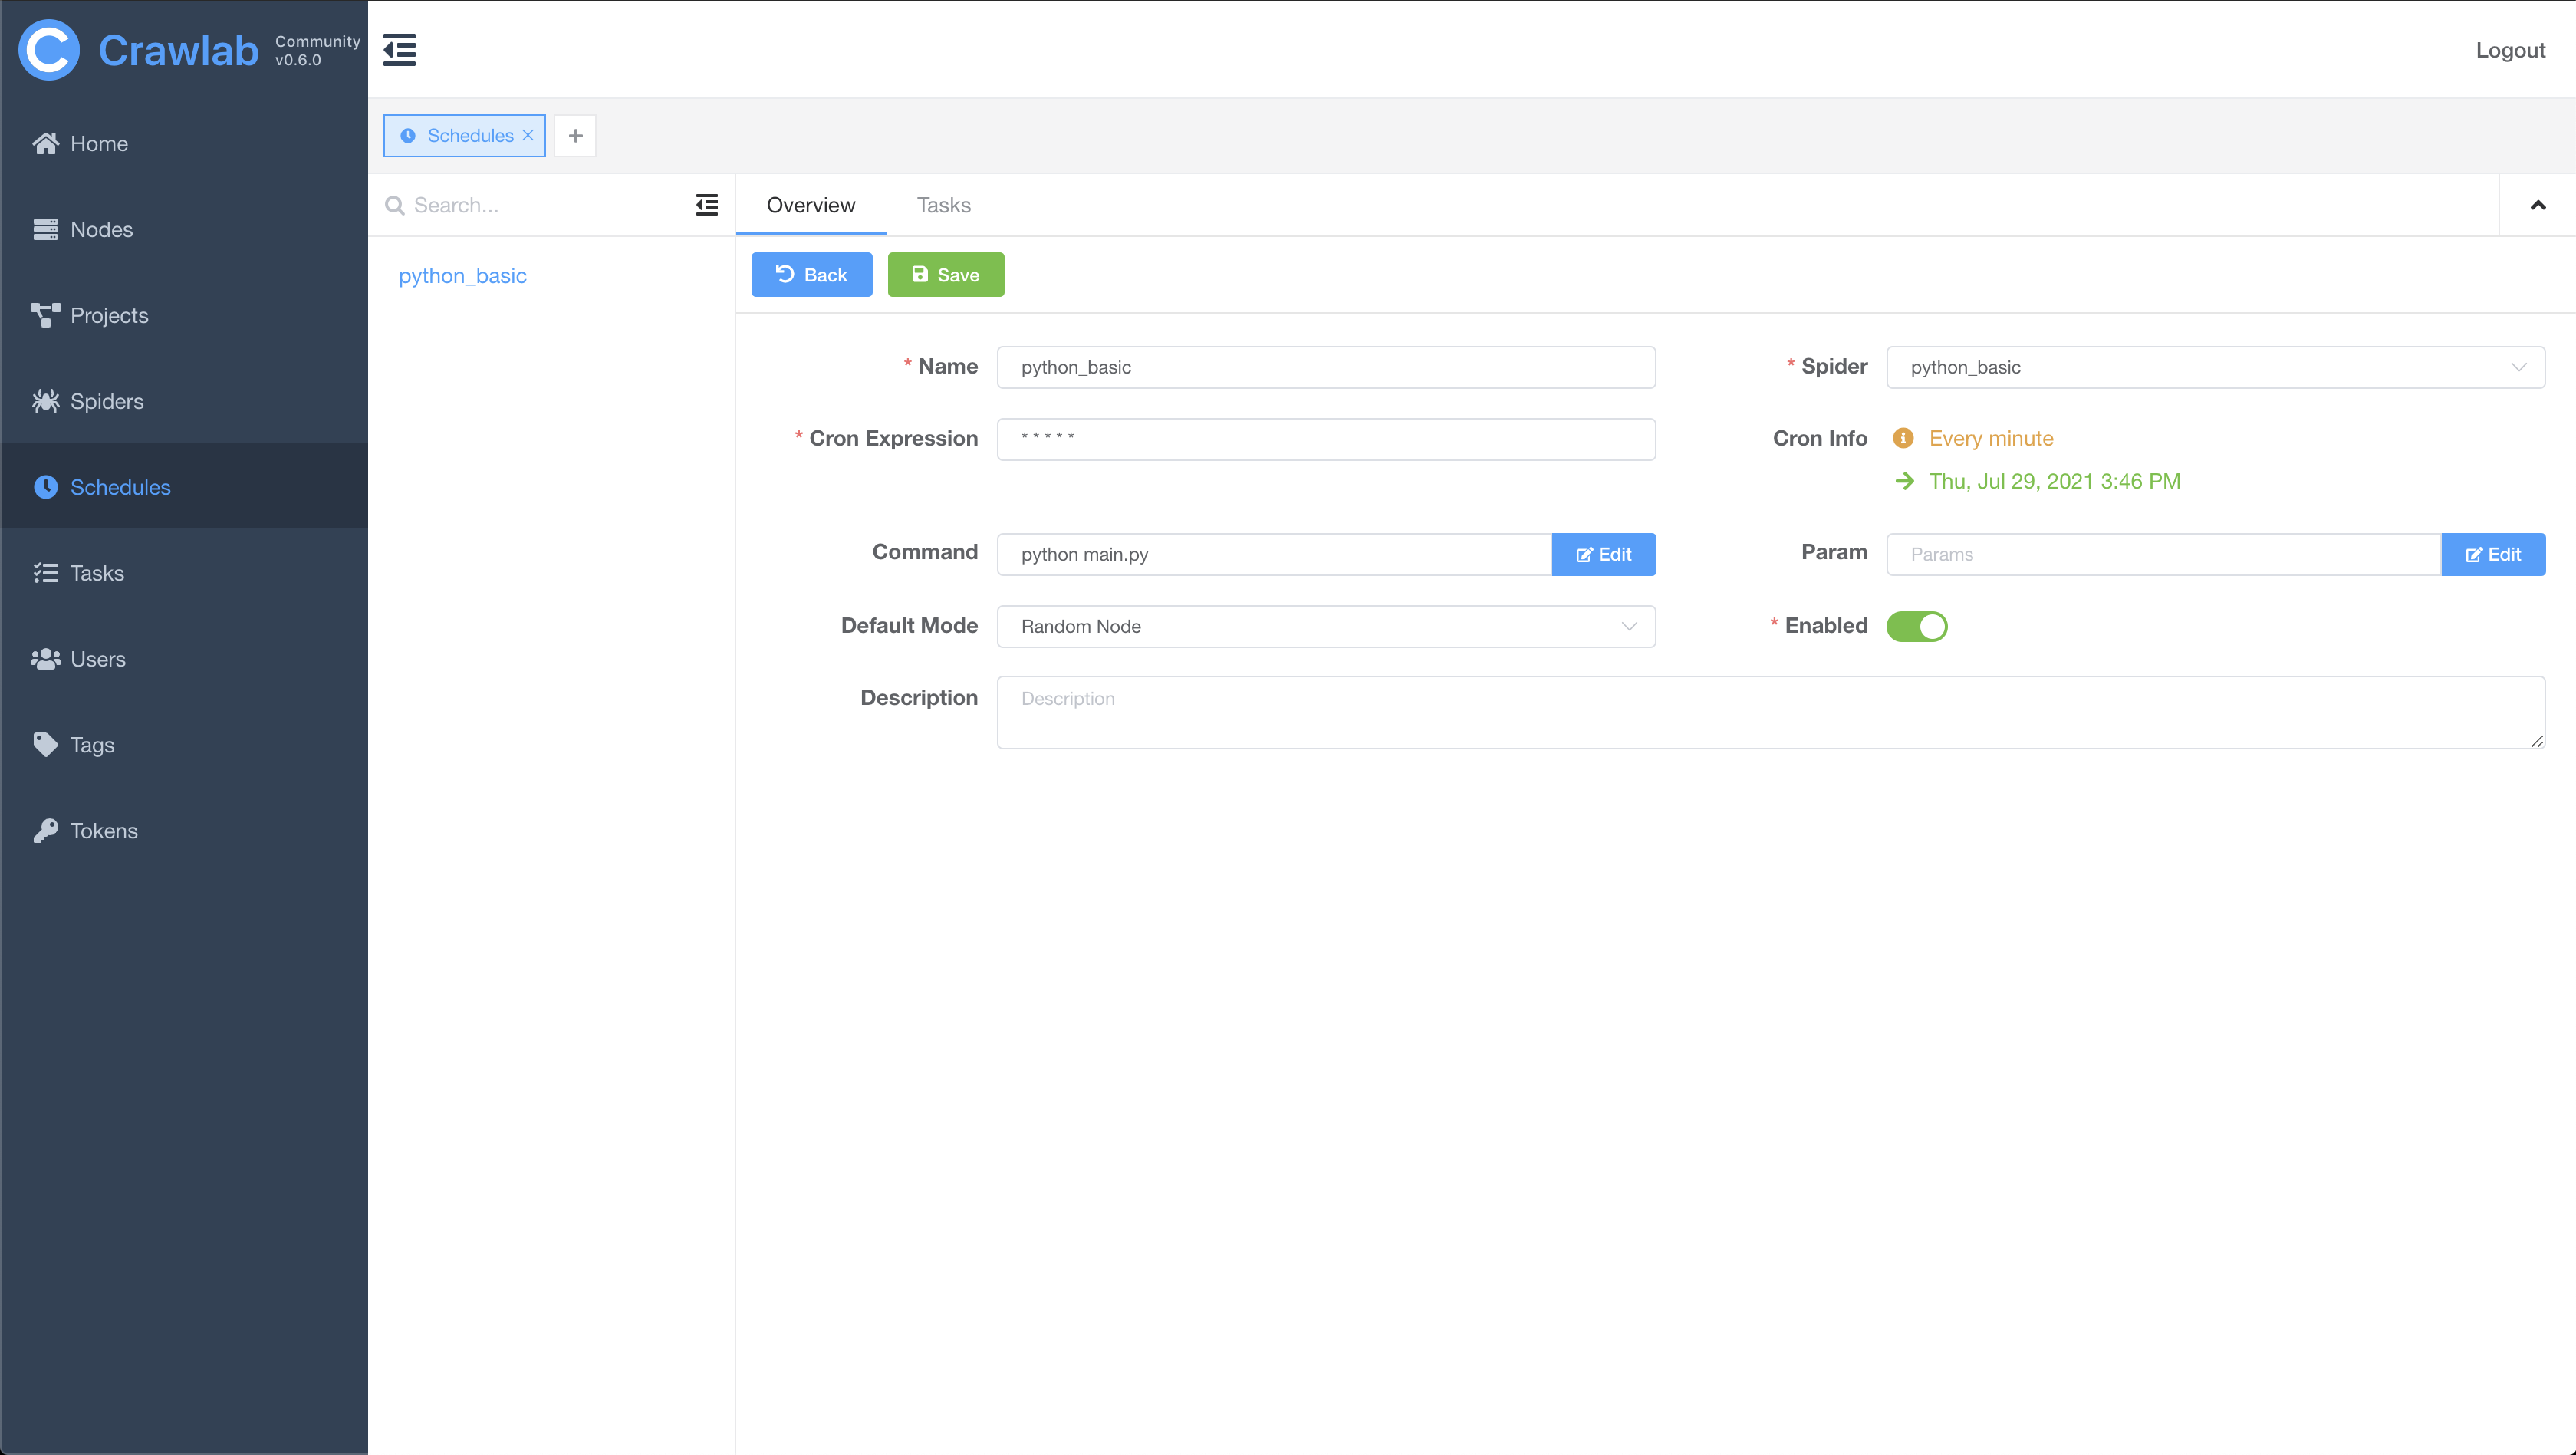
#### Cron Job
## Architecture
The architecture of Crawlab is consisted of a master node, worker nodes, [SeaweedFS](https://github.com/chrislusf/seaweedfs) (a distributed file system) and MongoDB database.
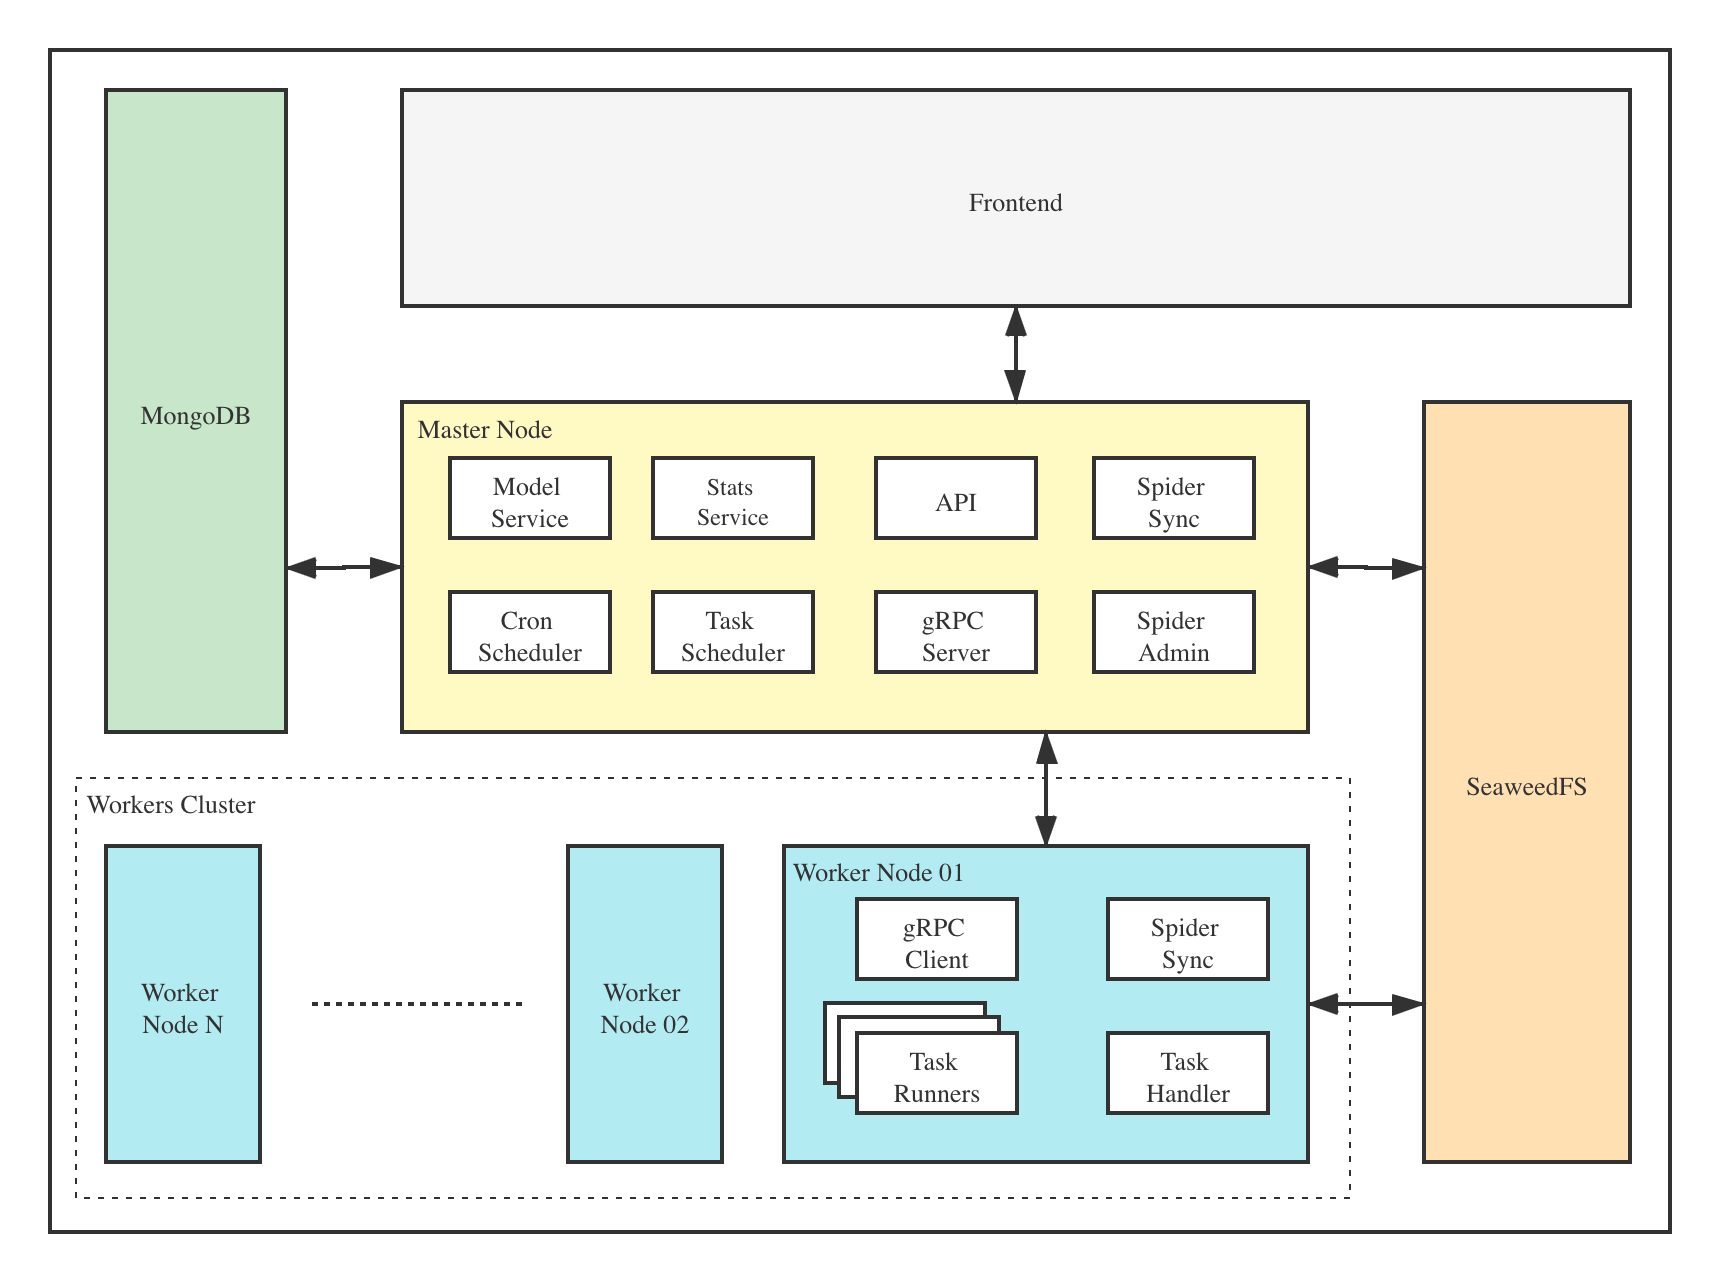
The frontend app interacts with the master node, which communicates with other components such as MongoDB, SeaweedFS and worker nodes. Master node and worker nodes communicate with each other via [gRPC](https://grpc.io) (a RPC framework). Tasks are scheduled by the task scheduler module in the master node, and received by the task handler module in worker nodes, which executes these tasks in task runners. Task runners are actually processes running spider or crawler programs, and can also send data through gRPC (integrated in SDK) to other data sources, e.g. MongoDB.
### Master Node
The Master Node is the core of the Crawlab architecture. It is the center control system of Crawlab.
The Master Node provides below services:
1. Task Scheduling;
2. Worker Node Management and Communication;
3. Spider Deployment;
4. Frontend and API Services;
5. Task Execution (you can regard the Master Node as a Worker Node)
The Master Node communicates with the frontend app, and send crawling tasks to Worker Nodes. In the mean time, the Master Node uploads (deploys) spiders to the distributed file system SeaweedFS, for synchronization by worker nodes.
### Worker Node
The main functionality of the Worker Nodes is to execute crawling tasks and store results and logs, and communicate with the Master Node through gRPC. By increasing the number of Worker Nodes, Crawlab can scale horizontally, and different crawling tasks can be assigned to different nodes to execute.
### MongoDB
MongoDB is the operational database of Crawlab. It stores data of nodes, spiders, tasks, schedules, etc. Task queue is also stored in MongoDB.
### SeaweedFS
SeaweedFS is an open source distributed file system authored by [Chris Lu](https://github.com/chrislusf). It can robustly store and share files across a distributed system. In Crawlab, SeaweedFS mainly plays the role as file synchronization system and the place where task log files are stored.
### Frontend
Frontend app is built upon [Element-Plus](https://github.com/element-plus/element-plus), a popular [Vue 3](https://github.com/vuejs/vue-next)-based UI framework. It interacts with API hosted on the Master Node, and indirectly controls Worker Nodes.
## Integration with Other Frameworks
[Crawlab SDK](https://github.com/crawlab-team/crawlab-sdk) provides some `helper` methods to make it easier for you to integrate your spiders into Crawlab, e.g. saving results.
### Scrapy
In `settings.py` in your Scrapy project, find the variable named `ITEM_PIPELINES` (a `dict` variable). Add content below.
```python
ITEM_PIPELINES = {
'crawlab.scrapy.pipelines.CrawlabPipeline': 888,
}
```
Then, start the Scrapy spider. After it's done, you should be able to see scraped results in **Task Detail -> Data**
### General Python Spider
Please add below content to your spider files to save results.
```python
# import result saving method
from crawlab import save_item
# this is a result record, must be dict type
result = {'name': 'crawlab'}
# call result saving method
save_item(result)
```
Then, start the spider. After it's done, you should be able to see scraped results in **Task Detail -> Data**
### Other Frameworks / Languages
A crawling task is actually executed through a shell command. The Task ID will be passed to the crawling task process in the form of environment variable named `CRAWLAB_TASK_ID`. By doing so, the data can be related to a task.
## Comparison with Other Frameworks
There are existing spider management frameworks. So why use Crawlab?
The reason is that most of the existing platforms are depending on Scrapyd, which limits the choice only within python and scrapy. Surely scrapy is a great web crawl framework, but it cannot do everything.
Crawlab is easy to use, general enough to adapt spiders in any language and any framework. It has also a beautiful frontend interface for users to manage spiders much more easily.
|Framework | Technology | Pros | Cons | Github Stats |
|:---|:---|:---|-----| :---- |
| [Crawlab](https://github.com/crawlab-team/crawlab) | Golang + Vue|Not limited to Scrapy, available for all programming languages and frameworks. Beautiful UI interface. Naturally support distributed spiders. Support spider management, task management, cron job, result export, analytics, notifications, configurable spiders, online code editor, etc.|Not yet support spider versioning|   |
| [ScrapydWeb](https://github.com/my8100/scrapydweb) | Python Flask + Vue|Beautiful UI interface, built-in Scrapy log parser, stats and graphs for task execution, support node management, cron job, mail notification, mobile. Full-feature spider management platform.|Not support spiders other than Scrapy. Limited performance because of Python Flask backend.|   |
| [Gerapy](https://github.com/Gerapy/Gerapy) | Python Django + Vue|Gerapy is built by web crawler guru [Germey Cui](https://github.com/Germey). Simple installation and deployment. Beautiful UI interface. Support node management, code edit, configurable crawl rules, etc.|Again not support spiders other than Scrapy. A lot of bugs based on user feedback in v1.0. Look forward to improvement in v2.0|   |
| [SpiderKeeper](https://github.com/DormyMo/SpiderKeeper) | Python Flask|Open-source Scrapyhub. Concise and simple UI interface. Support cron job.|Perhaps too simplified, not support pagination, not support node management, not support spiders other than Scrapy.|   |
## Contributors
<a href="https://github.com/tikazyq">
<img src="https://avatars3.githubusercontent.com/u/3393101?s=460&v=4" height="80">
</a>
<a href="https://github.com/wo10378931">
<img src="https://avatars2.githubusercontent.com/u/8297691?s=460&v=4" height="80">
</a>
<a href="https://github.com/yaziming">
<img src="https://avatars2.githubusercontent.com/u/54052849?s=460&v=4" height="80">
</a>
<a href="https://github.com/hantmac">
<img src="https://avatars2.githubusercontent.com/u/7600925?s=460&v=4" height="80">
</a>
<a href="https://github.com/duanbin0414">
<img src="https://avatars3.githubusercontent.com/u/50389867?s=460&v=4" height="80">
</a>
<a href="https://github.com/zkqiang">
<img src="https://avatars3.githubusercontent.com/u/32983588?s=460&u=83082ddc0a3020279374b94cce70f1aebb220b3d&v=4" height="80">
</a>
## Supported by JetBrains
<p align="center">
<a href="https://www.jetbrains.com" target="_blank">
<img src="https://resources.jetbrains.com/storage/products/company/brand/logos/jb_beam.png" height="360">
</a>
</p>
## Community
If you feel Crawlab could benefit your daily work or your company, please add the author's Wechat account noting "Crawlab" to enter the discussion group.
<p align="center">
<img src="https://crawlab.oss-cn-hangzhou.aliyuncs.com/gitbook/qrcode.png" height="360">
</p>