discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
clips/pattern · source
Snapshot 0 · 2026-11-04T12:47:21Z · Python · BSD-3-Clause
Content fingerprint
b345c0a9e6e16cd9c637c02acd3b1c6414f16c5d9e79027180e603afaa134601GitHub description at capture
Web mining module for Python, with tools for scraping, natural language processing, machine learning, network analysis and visualization.
README at capture
# WARNING: This repository is no longer maintained.
This project is archived and will not receive further updates, bug fixes, or security patches. Issues and pull requests may not be reviewed.
Use this software at your own risk.
__________________________________________________
Pattern
=======
[](https://travis-ci.org/clips/pattern/branches)
[](https://coveralls.io/github/clips/pattern?branch=master)
[](https://pypi.python.org/pypi/pattern)
[](https://github.com/clips/pattern/blob/master/LICENSE.txt)
Pattern is a web mining module for Python. It has tools for:
* Data Mining: web services (Google, Twitter, Wikipedia), web crawler, HTML DOM parser
* Natural Language Processing: part-of-speech taggers, n-gram search, sentiment analysis, WordNet
* Machine Learning: vector space model, clustering, classification (KNN, SVM, Perceptron)
* Network Analysis: graph centrality and visualization.
It is well documented, thoroughly tested with 350+ unit tests and comes bundled with 50+ examples. The source code is licensed under BSD.
Example
-------
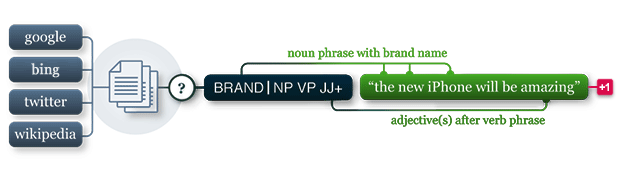
This example trains a classifier on adjectives mined from Twitter using Python 3. First, tweets that contain hashtag #win or #fail are collected. For example: *"$20 tip off a sweet little old lady today #win"*. The word part-of-speech tags are then parsed, keeping only adjectives. Each tweet is transformed to a vector, a dictionary of adjective → count items, labeled `WIN` or `FAIL`. The classifier uses the vectors to learn which other tweets look more like `WIN` or more like `FAIL`.
```python
from pattern.web import Twitter
from pattern.en import tag
from pattern.vector import KNN, count
twitter, knn = Twitter(), KNN()
for i in range(1, 3):
for tweet in twitter.search('#win OR #fail', start=i, count=100):
s = tweet.text.lower()
p = '#win' in s and 'WIN' or 'FAIL'
v = tag(s)
v = [word for word, pos in v if pos == 'JJ'] # JJ = adjective
v = count(v) # {'sweet': 1}
if v:
knn.train(v, type=p)
print(knn.classify('sweet potato burger'))
print(knn.classify('stupid autocorrect'))
```
Installation
------------
Pattern supports Python 2.7 and Python 3.6. To install Pattern so that it is available in all your scripts, unzip the download and from the command line do:
```bash
cd pattern-3.6
python setup.py install
```
If you have pip, you can automatically download and install from the [PyPI repository](https://pypi.python.org/pypi/pattern):
```bash
pip install pattern
```
If none of the above works, you can make Python aware of the module in three ways:
- Put the pattern folder in the same folder as your script.
- Put the pattern folder in the standard location for modules so it is available to all scripts:
* `c:\python36\Lib\site-packages\` (Windows),
* `/Library/Python/3.6/site-packages/` (Mac OS X),
* `/usr/lib/python3.6/site-packages/` (Unix).
- Add the location of the module to `sys.path` in your script, before importing it:
```python
MODULE = '/users/tom/desktop/pattern'
import sys; if MODULE not in sys.path: sys.path.append(MODULE)
from pattern.en import parsetree
```
Documentation
-------------
For documentation and examples see the [user documentation](https://github.com/clips/pattern/wiki).
Version
-------
3.6
License
-------
**BSD**, see `LICENSE.txt` for further details.
Reference
---------
De Smedt, T., Daelemans, W. (2012). Pattern for Python. *Journal of Machine Learning Research, 13*, 2031–2035.
Contribute
----------
The source code is hosted on GitHub and contributions or donations are welcomed.
Bundled dependencies
--------------------
Pattern is bundled with the following data sets, algorithms and Python packages:
- **Brill tagger**, Eric Brill
- **Brill tagger for Dutch**, Jeroen Geertzen
- **Brill tagger for German**, Gerold Schneider & Martin Volk
- **Brill tagger for Spanish**, trained on Wikicorpus (Samuel Reese & Gemma Boleda et al.)
- **Brill tagger for French**, trained on Lefff (Benoît Sagot & Lionel Clément et al.)
- **Brill tagger for Italian**, mined from Wiktionary
- **English pluralization**, Damian Conway
- **Spanish verb inflection**, Fred Jehle
- **French verb inflection**, Bob Salita
- **Graph JavaScript framework**, Aslak Hellesoy & Dave Hoover
- **LIBSVM**, Chih-Chung Chang & Chih-Jen Lin
- **LIBLINEAR**, Rong-En Fan et al.
- **NetworkX centrality**, Aric Hagberg, Dan Schult & Pieter Swart
- **spelling corrector**, Peter Norvig
Acknowledgements
----------------
**Authors:**
- Tom De Smedt (tom@organisms.be)
- Walter Daelemans (walter.daelemans@ua.ac.be)
**Contributors (chronological):**
- Frederik De Bleser
- Jason Wiener
- Daniel Friesen
- Jeroen Geertzen
- Thomas Crombez
- Ken Williams
- Peteris Erins
- Rajesh Nair
- F. De Smedt
- Radim Řehůřek
- Tom Loredo
- John DeBovis
- Thomas Sileo
- Gerold Schneider
- Martin Volk
- Samuel Joseph
- Shubhanshu Mishra
- Robert Elwell
- Fred Jehle
- Antoine Mazières + fabelier.org
- Rémi de Zoeten + closealert.nl
- Kenneth Koch
- Jens Grivolla
- Fabio Marfia
- Steven Loria
- Colin Molter + tevizz.com
- Peter Bull
- Maurizio Sambati
- Dan Fu
- Salvatore Di Dio
- Vincent Van Asch
- Frederik Elwert