discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
braincompany/sessiongrep · source
Snapshot 0 · 2026-11-04T12:47:28Z · Rust · Apache-2.0
Content fingerprint
ffcf07a93b29974c00b8ba8ee00ecea73cdf7cdae0b1f13e6d4581d311d46cbeGitHub description at capture
Local-first memory layer for CLI agents. Indexes Claude Code, Codex CLI, Cursor, Antigravity, and Pi sessions into SQLite + FTS5, searchable from a CLI, TUI, or MCP server.
README at capture
# sessiongrep [](https://github.com/braincompany/sessiongrep/actions/workflows/ci.yml) [](LICENSE) **You solved that bug last week. Your next agent session has no idea.** A local-first memory layer for CLI agents. `sessiongrep` indexes your Claude Code, Codex CLI, Cursor, Antigravity, and Pi session histories into a single SQLite + FTS5 database, then gives you one CLI/TUI to find old work by topic, repo, provider, or recency. It also ships an MCP server so your agent can search its own history. The real payoff is portable context: your session history isn't trapped in one tool. Work you started in Claude Code can continue in Codex, and an agent can recover — and even critique — its own prior reasoning across every tool you use. 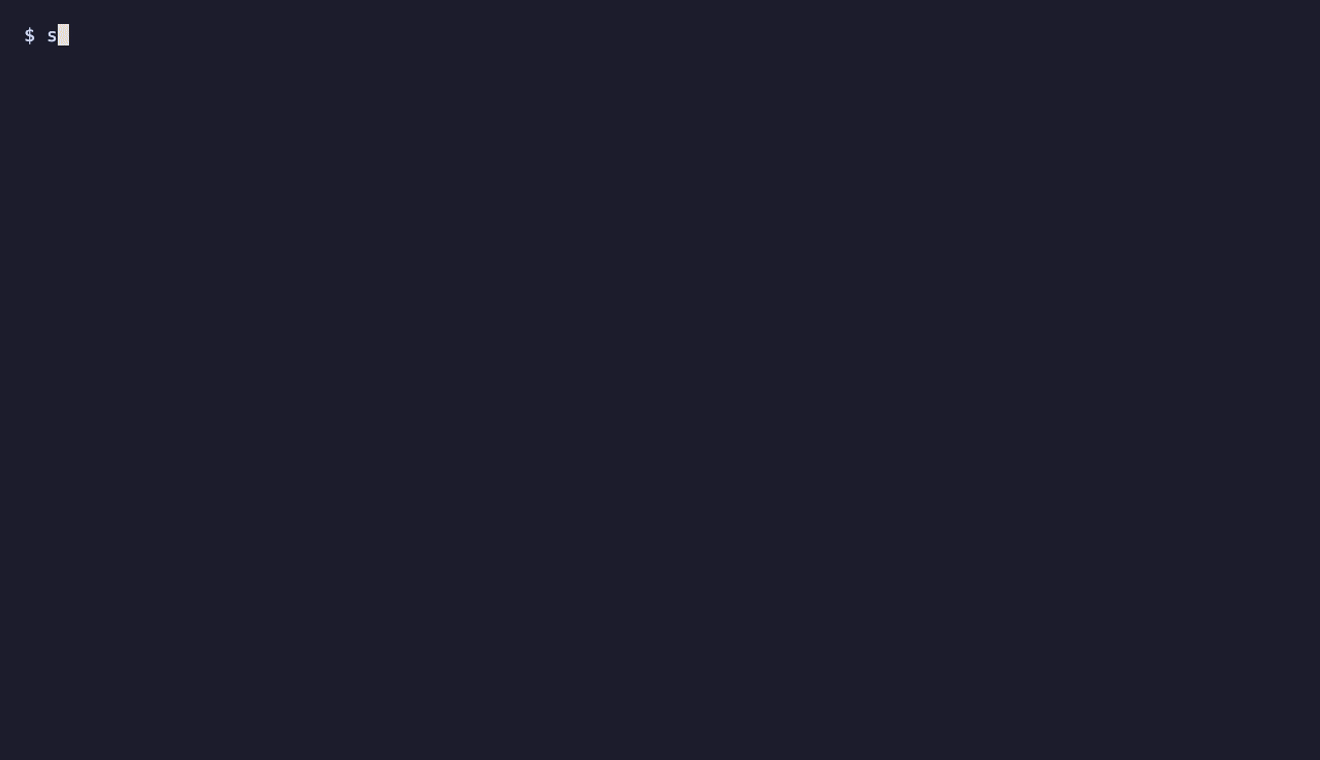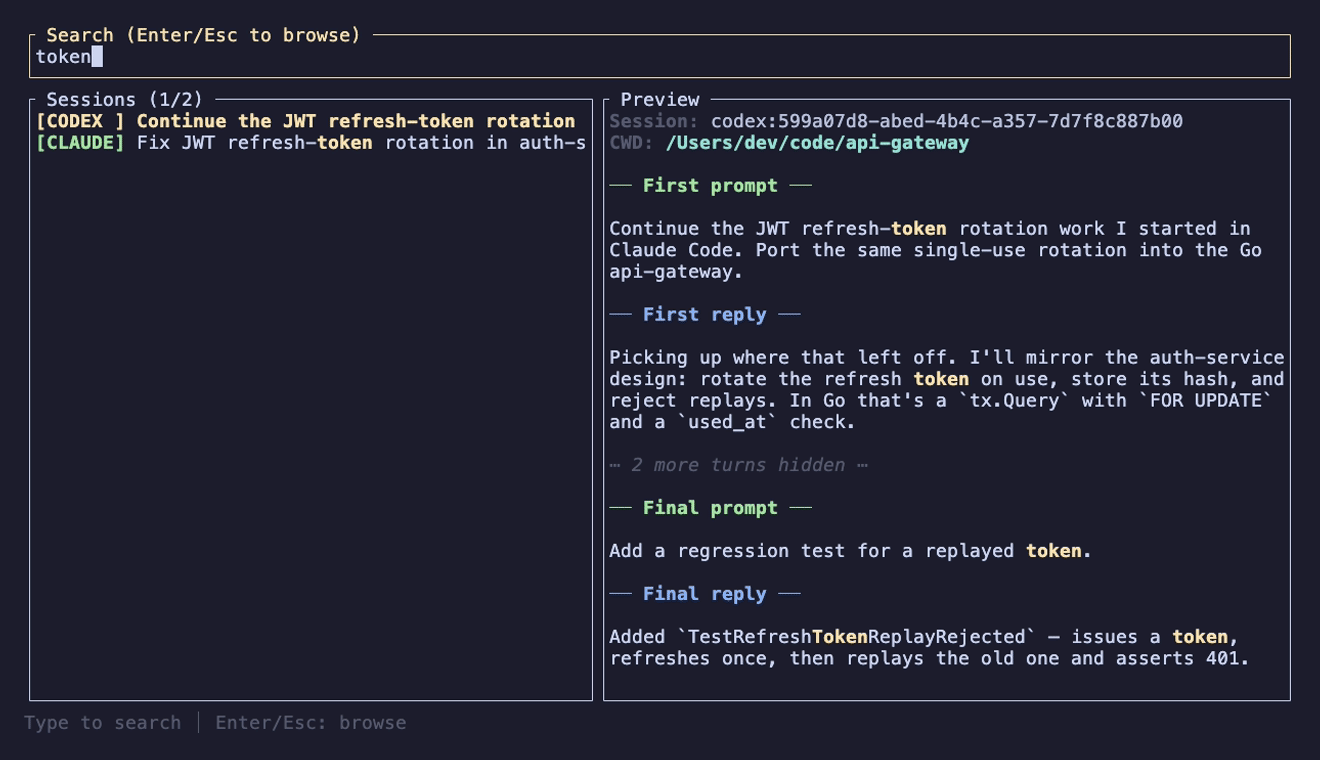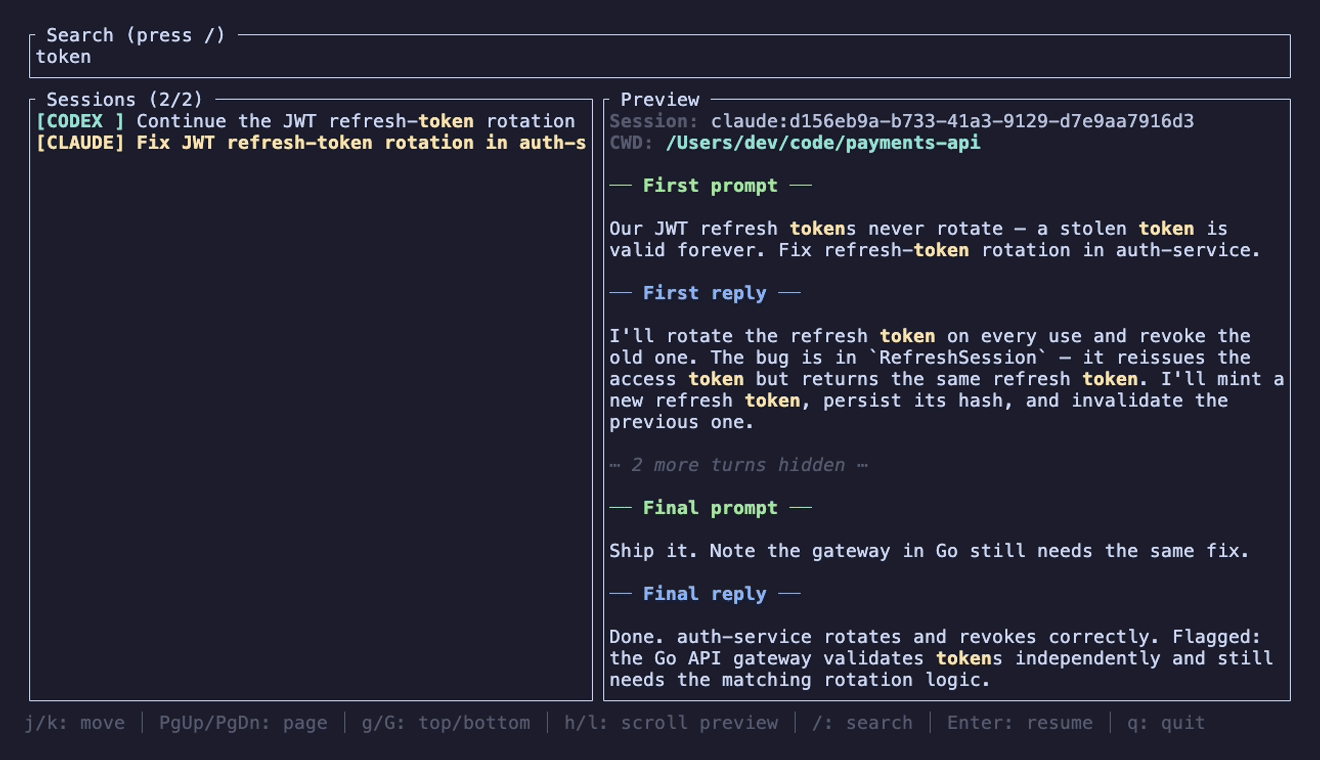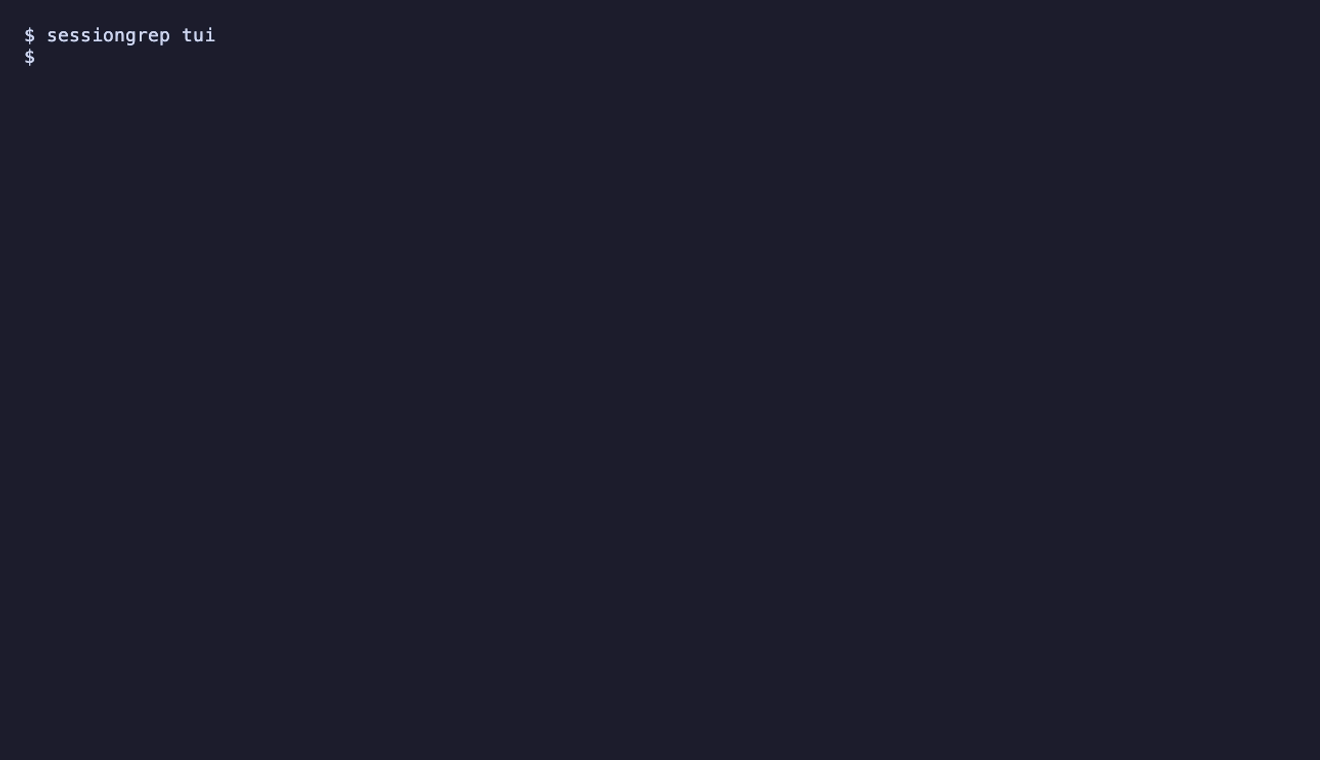 <!-- Demo GIF is generated from sanitized sample data (generation scripts kept outside the repo). --> Read the announcement: [Sessiongrep: a local-first memory layer for CLI agents](https://brain.co/blog/sessiongrep-a-local-first-memory-layer-for-cli-agents). ## Why Session transcripts already live on your machine — scattered across `~/.claude/projects`, `~/.codex/sessions`, `~/.cursor/projects` as noisy JSONL with opaque filenames. The information is not missing, it's stranded. Humans don't want to read it; agents don't know how to retrieve it. Grep over JSONL drowns in tool payloads. Shell history captures commands but not reasoning. Cloud-synced or vector-backed alternatives bring secrets and URLs into systems that aren't yours. `sessiongrep` keeps recall local. One static binary, one SQLite file, no daemon, no server. The index is a disposable cache — delete it and rebuild it whenever you want. ## How it works Provider adapters normalize Claude, Codex, Cursor, Antigravity, and Pi transcripts into a single `Session` model and write them into SQLite (WAL mode) with an FTS5 virtual table over transcript text, title, summary, and preview. Every read command runs an incremental reindex first — files whose mtime and size haven't changed are skipped, so search and list stay fast even as your history grows. Only the conversation is indexed: your prompts and the agent's replies. Tool calls and their output, injected context (AGENTS.md, skill bodies, system reminders), and sub-agent transcripts are left out, so a hit points at what was discussed rather than at every file an agent happened to read. Titles come from each tool's own session names where they exist (Claude Code's `/rename` and generated titles, Codex thread names), falling back to the first prompt. ## Installation You need session history from at least one of Claude Code, Codex CLI, Cursor, Antigravity, or Pi. ### Prebuilt binaries (macOS, Linux) ```bash curl --proto '=https' --tlsv1.2 -LsSf https://github.com/braincompany/sessiongrep/releases/latest/download/sessiongrep-installer.sh | sh ``` The installer picks the build for your platform, verifies its checksum, and adds `~/.cargo/bin` to your PATH if needed. Archives for manual download are on the [releases page](https://github.com/braincompany/sessiongrep/releases). ### With Cargo Requires a [Rust toolchain](https://rustup.rs/) 1.88 or newer: ```bash cargo install sessiongrep --locked ``` To build the latest `main` instead: `cargo install --locked --git https://github.com/braincompany/sessiongrep`. Nix users can install from the flake: `nix profile install github:braincompany/sessiongrep`. Every method installs two binaries into `~/.cargo/bin/`: - `sessiongrep` — CLI and TUI - `sessiongrep-mcp` — MCP server To upgrade, run the same command again. ### Index your sessions The index updates automatically — every command (search, list, tui, etc.) runs an incremental reindex before executing. No cron jobs or manual steps needed. To force a full rebuild from scratch (see [Privacy & data](#privacy--data) for what this drops): ```bash sessiongrep reindex --full ``` ## Quick start ```bash sessiongrep list --limit 20 # recent sessions (auto-indexes on first run) sessiongrep search "auth bug" # keyword search sessiongrep search "redis" --provider codex sessiongrep search "datadog" --provider cursor sessiongrep search "temporal" --provider pi sessiongrep show claude:79accec8-5bf5-415b-a4a5-fe370eb2c998 sessiongrep resume 79accec8 --dry-run sessiongrep export 79accec8 --format markdown sessiongrep doctor # health check sessiongrep tui # interactive browser sessiongrep --help # every command and flag ``` Search matches whole words, partial words (`sqli` finds `sqlite`), and small typos in titles and paths, then ranks results by where the match landed, how recent the session is, and whether it belongs to the repo you're in. ## MCP server setup The MCP server lets AI agents search and retrieve your past sessions programmatically — no copy-pasting context from old conversations. ### Claude Code ```bash claude mcp add --scope user --transport stdio sessiongrep -- sessiongrep-mcp ``` ### Codex CLI ```bash codex mcp add sessiongrep -- sessiongrep-mcp ``` ### Verify Start a new session and try a prompt like: > "Find my previous session where I was setting up Datadog metrics" The agent will call `search_sessions` to find matches and `get_session` to pull in relevant context. ### MCP tools | Tool | Description | |------|-------------| | `search_sessions` | Search sessions by keyword, with optional provider filter and limit | | `get_session` | Get a session's transcript and metadata by ID or prefix. Long transcripts are paged (~40k characters by default) with `offset`, `char_offset`, `max_lines`, and `max_chars` | | `list_sessions` | List recent sessions, filterable by provider and path prefix | | `timeline_for_repo` | Day-bucketed metadata timeline for a repo path prefix — scoped view of what changed over time | | `get_resume_command` | Get the CLI command to resume a session in its native tool | ## Config Optional config file at `~/.config/sessiongrep/config.toml`. Every key is optional; these are the defaults: ```toml [providers.claude] enabled = true paths = ["~/.claude/projects"] [providers.codex] enabled = true paths = ["~/.codex/sessions"] # or $CODEX_HOME/sessions when CODEX_HOME is set [providers.cursor] enabled = true paths = ["~/.cursor/projects"] [providers.antigravity] enabled = true paths = ["~/.gemini/antigravity/brain"] [providers.pi] enabled = true paths = ["~/.pi/agent/sessions"] [index] db_path = "~/.local/share/sessiongrep/index.db" [search] default_limit = 25 # results for list/search when --limit isn't given prefer_current_repo = true # rank sessions from the repo you're in higher ``` ## Privacy & data - Everything stays on your machine. No network calls, no telemetry, no cloud sync. - The tool is read-only: it never writes to your session files or to the tools' own databases. - The SQLite index at `~/.local/share/sessiongrep/index.db` is built from your transcripts and can be deleted anytime. - The index keeps sessions whose source files have since been deleted, so they stay searchable. Claude Code, for example, removes transcripts 30 days after their last activity by default (its `cleanupPeriodDays` setting). Deleting the index or running `reindex --full` rebuilds it from the files still on disk and drops those sessions. - The database and config live under `~/.local/share` and `~/.config`. ## Limitations - Resume delegates to the native provider CLI (`claude --resume <id>`, `codex resume <id>`, or `pi --session <id>`). Cursor and Antigravity resume are not currently supported, and a session whose transcript file has been deleted can be searched but not resumed. - Sub-agent transcripts (Claude, Codex, Cursor, and Pi) are excluded from indexing to avoid duplicate records. - Search is keyword-based (SQLite FTS5 plus fuzzy matching on titles and paths); there is no semantic or embedding search. ## Status Early but usable (v0.1). The CLI surface and MCP tool names are likely to stay stable. When an upgrade changes how sessions are parsed, sessiongrep re-parses your session files automatically on the next run. ## Contributing Issues and pull requests are welcome. For bugs, please include your provider versions and a `sessiongrep doctor` output. For features, a quick issue to discuss scope before sending a PR keeps things moving. ## License Apache-2.0. See [LICENSE](LICENSE).