discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
GeeeekExplorer/nano-vllm · source
Snapshot 0 · 2026-11-04T12:47:27Z · Python · MIT
Content fingerprint
b6c5181482d451580c71688f5d8b48a50c05341d81695ed8a01962abd09ba486GitHub description at capture
Nano vLLM
README at capture
<p align="center">
<img width="300" src="assets/logo.png">
</p>
<p align="center">
<a href="https://trendshift.io/repositories/15323" target="_blank"><img src="https://trendshift.io/api/badge/repositories/15323" alt="GeeeekExplorer%2Fnano-vllm | Trendshift" style="width: 250px; height: 55px;" width="250" height="55"/></a>
</p>
# Nano-vLLM
A lightweight vLLM implementation built from scratch.
## Key Features
* 🚀 **Fast offline inference** - Comparable inference speeds to vLLM
* 📖 **Readable codebase** - Clean implementation in ~ 1,200 lines of Python code
* ⚡ **Optimization Suite** - Prefix caching, Tensor Parallelism, Torch compilation, CUDA graph, etc.
## Installation
```bash
pip install git+https://github.com/GeeeekExplorer/nano-vllm.git
```
## Model Download
To download the model weights manually, use the following command:
```bash
huggingface-cli download --resume-download Qwen/Qwen3-0.6B \
--local-dir ~/huggingface/Qwen3-0.6B/ \
--local-dir-use-symlinks False
```
## Quick Start
See `example.py` for usage. The API mirrors vLLM's interface with minor differences in the `LLM.generate` method:
```python
from nanovllm import LLM, SamplingParams
llm = LLM("/YOUR/MODEL/PATH", enforce_eager=True, tensor_parallel_size=1)
sampling_params = SamplingParams(temperature=0.6, max_tokens=256)
prompts = ["Hello, Nano-vLLM."]
outputs = llm.generate(prompts, sampling_params)
outputs[0]["text"]
```
## Benchmark
See `bench.py` for benchmark.
**Test Configuration:**
- Hardware: RTX 4070 Laptop (8GB)
- Model: Qwen3-0.6B
- Total Requests: 256 sequences
- Input Length: Randomly sampled between 100–1024 tokens
- Output Length: Randomly sampled between 100–1024 tokens
**Performance Results:**
| Inference Engine | Output Tokens | Time (s) | Throughput (tokens/s) |
|----------------|-------------|----------|-----------------------|
| vLLM | 133,966 | 98.37 | 1361.84 |
| Nano-vLLM | 133,966 | 93.41 | 1434.13 |
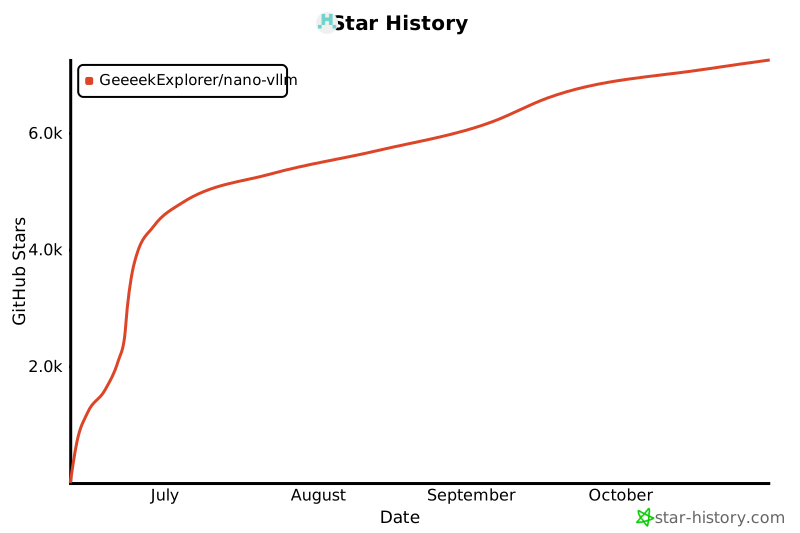
## Star History
[](https://www.star-history.com/#GeeeekExplorer/nano-vllm&Date)