discover · compare · collections · requirements · contribute · feed · watching · stats · help with your tokens
Cyan4973/xxHash · source
Snapshot 0 · 2026-11-04T12:47:23Z · C ·
Content fingerprint
53d69c84d2cab9cdb738fba653029aae39b610fdbc70037e7ffe5f73f991d5b0GitHub description at capture
Extremely fast non-cryptographic hash algorithm
README at capture
xxHash - Extremely fast hash algorithm
======================================
[Website](https://xxhash.com/) · [API documentation](lib/README.md#documentation) · [`xxhsum` manual](cli/xxhsum.1.md) · [Format specification](doc/xxhash_spec.md)
xxHash is an extremely fast non-cryptographic hash algorithm, working at RAM
speed limits. It is highly portable and produces identical hashes on all
platforms, including little- and big-endian systems. Once finalized, algorithm
outputs remain stable across xxHash releases.
The library includes the following algorithms:
- XXH32 generates 32-bit hashes, using 32-bit arithmetic.
- XXH64 generates 64-bit hashes, using 64-bit arithmetic.
- XXH3, available since v0.8.0, generates 64-bit or 128-bit hashes using
vectorized arithmetic. The 128-bit variant is called XXH128.
For new applications, `XXH3_64bits()` is the recommended default. Use
`XXH3_128bits()` when a 128-bit hash is required.
Benchmarks
----------
The benchmarked reference system uses an Intel i7-9700K CPU running Ubuntu
x64 20.04. The [open source benchmark program] is compiled with Clang v10.0
using `-O3`.
| Hash Name | Width | Bandwidth | Small Data Velocity | Comment |
| --- | ---: | ---: | ---: | --- |
| **XXH3** (AVX2) | 64 | 59.4 GB/s | 133.1 | |
| **XXH128** (AVX2) | 128 | 57.9 GB/s | 118.1 | |
| **XXH3** (SSE2) | 64 | 31.5 GB/s | 133.1 | |
| **XXH128** (SSE2) | 128 | 29.6 GB/s | 118.1 | |
| *memcpy*, from RAM | N/A | 28.0 GB/s | N/A | *for reference* |
| City64 | 64 | 22.0 GB/s | 76.6 | |
| T1ha2 | 64 | 22.0 GB/s | 99.0 | Slightly worse [collisions] |
| City128 | 128 | 21.7 GB/s | 57.7 | |
| **XXH64** | 64 | 19.4 GB/s | 71.0 | |
| SpookyHash | 64 | 19.3 GB/s | 53.2 | |
| Mum | 64 | 18.0 GB/s | 67.0 | Slightly worse [collisions] |
| **XXH32** | 32 | 9.7 GB/s | 71.9 | |
| City32 | 32 | 9.1 GB/s | 66.0 | |
| Murmur3 | 32 | 3.9 GB/s | 56.1 | |
| SipHash | 64 | 3.0 GB/s | 43.2 | |
| FNV64 | 64 | 1.2 GB/s | 62.7 | Poor avalanche properties |
| Blake2 | 256 | 1.1 GB/s | 5.1 | Cryptographic |
| SHA1 | 160 | 0.8 GB/s | 5.6 | Cryptographic but broken |
| MD5 | 128 | 0.6 GB/s | 7.8 | Cryptographic but broken |
[open source benchmark program]: tests/bench
[collisions]: https://github.com/Cyan4973/xxHash/wiki/Collision-ratio-comparison#collision-study
For current measurements on additional platforms, see the
[benchmarks on xxhash.com](https://xxhash.com/#benchmarks).
Note 1: Small data velocity is a _rough_ evaluation of an algorithm's
efficiency on small data. For more detailed analysis, see the next section.
Note 2: Some algorithms feature _faster than RAM_ speed. They can only reach
their full speed potential when input is already in CPU cache (L3 or better).
Otherwise, they are limited by RAM speed.
### Small data
Performance on large data is only one part of the picture.
Hashing is also very useful in constructions like hash tables and bloom filters.
In these use cases, it is common to hash many small inputs, sometimes only a
few bytes long. An algorithm's performance can be very different in such
scenarios, since initialization and finalization become fixed costs. Branch
misprediction also has a much greater impact.
XXH3 has been designed for excellent performance on both long and small inputs,
which can be observed in the following graph:
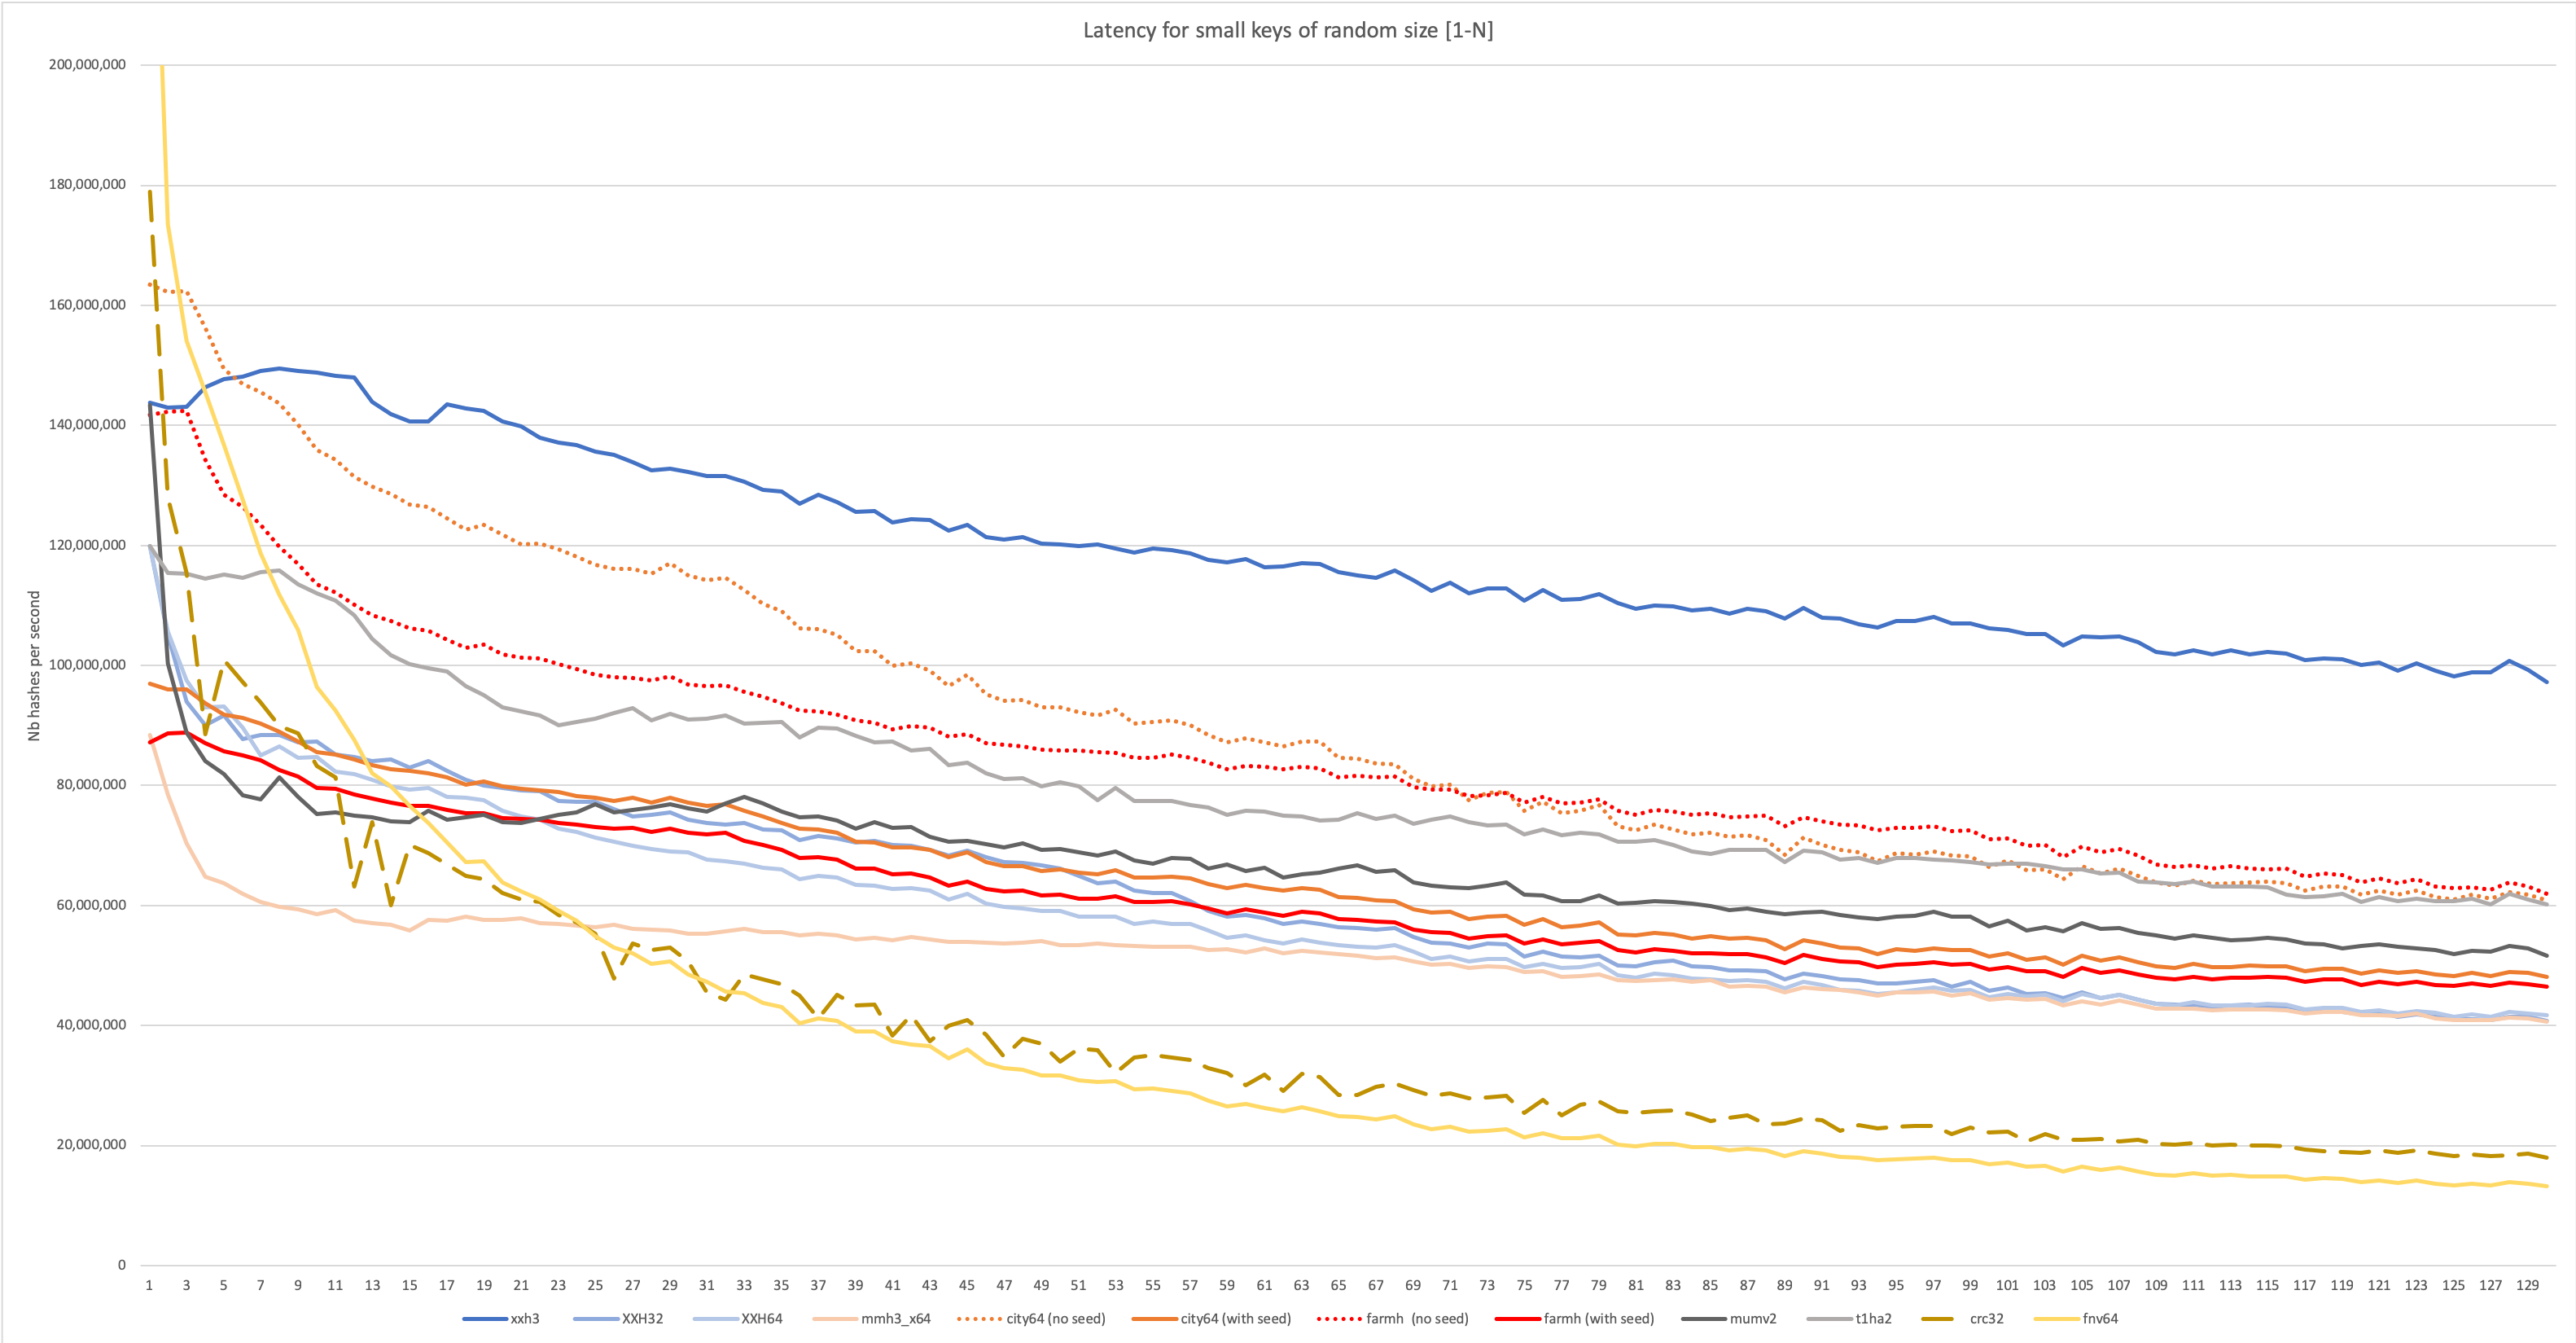
For a more detailed analysis, see the
[performance comparison on the wiki](https://github.com/Cyan4973/xxHash/wiki/Performance-comparison#benchmarks-concentrating-on-small-data-).
**xxHash is not a cryptographic hash function.** Do not use it for signatures,
password storage, or any other purpose that requires resistance to attacks.
|Branch |Status |
|------------|---------|
|release | [](https://github.com/Cyan4973/xxHash/actions?query=branch%3Arelease+) |
|dev | [](https://github.com/Cyan4973/xxHash/actions?query=branch%3Adev+) |
Getting started
---------------
The default `make` target builds both the library and the `xxhsum` command line
utility:
```sh
make
./xxhsum -H3 README.md
```
The library can then be linked as `libxxhash`, or compiled directly from
`xxhash.c`. For a header-only integration, define `XXH_INLINE_ALL` before
including `xxhash.h`:
```c
#define XXH_INLINE_ALL
#include "xxhash.h"
```
For CMake integration, see the [CMake guide](build/cmake/README.md). The
[`xxhsum` manual](cli/xxhsum.1.md) documents checksum generation, verification,
benchmarking and advanced command line options.
`xxhash.h` is generated from the source units in [`lib/`](lib/README.md).
It only keeps the documentation of public declarations, which IDEs display.
Smaller variants, limited to some hash families, can be generated with `make variants`,
or downloaded from each release (see [limited variants](lib/README.md#limited-variants)).
Contributors should modify these units: `make` regenerates `xxhash.h` (see [`AGENTS.md`](AGENTS.md)).
### Example
The simplest API hashes a contiguous block of memory in a single call:
```c
#include <stddef.h>
#include "xxhash.h"
XXH64_hash_t hash_buffer(const void* buffer, size_t size)
{
return XXH3_64bits(buffer, size);
}
```
The API also supports incremental hashing of streams of unknown size. Complete
single-shot and streaming examples are provided in the
[API documentation](lib/xxh_doc.h).
Quality
-------------------------
Speed is not the only property that matters.
For non-adversarial inputs, xxHash aims to produce a uniform distribution so
that any subset of the output bits can spread entries evenly in a table or
index. Like any fixed-width hash, it is still subject to collisions and the
[birthday paradox].
All variants successfully complete Austin Appleby's
[SMHasher](https://www.google.com/search?q=SMHasher) test suite, providing a
baseline measure of statistical quality.
Additional tests that evaluate speed and collision properties more thoroughly
are [also provided](tests).
Finally, xxHash provides its own [massive collision tester](tests/collisions),
able to generate and compare billions of hashes to test the limits of 64-bit hash algorithms.
On this front too, xxHash features good results, in line with the [birthday paradox].
A more detailed analysis is documented [in the wiki](https://github.com/Cyan4973/xxHash/wiki/Collision-ratio-comparison).
[birthday paradox]: https://en.wikipedia.org/wiki/Birthday_problem
Packages
--------
xxHash is available from many package managers. With
[vcpkg](https://github.com/microsoft/vcpkg), install the library with:
```sh
vcpkg install xxhash
```
Add the `xxhsum` feature to install the command line utility as well:
```sh
vcpkg install "xxhash[xxhsum]"
```
The current package versions available across distributions are tracked by
[Repology](https://repology.org/project/xxhash/versions).
[](https://repology.org/project/xxhash/versions)
Advanced build options
----------------------
### Library macros
The following macros can be set at compilation time to modify `libxxhash`'s behavior. They are generally disabled by default.
- `XXH_INLINE_ALL`: Make all functions `inline`, implementation is directly included within `xxhash.h`.
Inlining functions is beneficial for speed, notably for small keys.
It's _extremely effective_ when key's length is expressed as _a compile time constant_,
with performance improvements observed in the +200% range .
See [this article](https://fastcompression.blogspot.com/2018/03/xxhash-for-small-keys-impressive-power.html) for details.
- `XXH_PRIVATE_API`: same outcome as `XXH_INLINE_ALL`. Still available for legacy support.
The name underlines that `XXH_*` symbol names will not be exported.
- `XXH_STATIC_LINKING_ONLY`: gives access to internal state declaration, required for static allocation.
Incompatible with dynamic linking, due to risks of ABI changes.
- `XXH_NAMESPACE`: Prefixes all symbols with the value of `XXH_NAMESPACE`.
This macro can only use compilable character set.
Useful to evade symbol naming collisions,
in case of multiple inclusions of xxHash's source code.
Client applications still use the regular function names,
as symbols are automatically translated through `xxhash.h`.
- `XXH_FORCE_ALIGN_CHECK`: Use a faster direct read path when input is aligned.
This option can result in dramatic performance improvement on architectures unable to load memory from unaligned addresses
when input to hash happens to be aligned on 32 or 64-bit boundaries.
It is (slightly) detrimental on platform with good unaligned memory access performance (same instruction for both aligned and unaligned accesses).
This option is automatically disabled on `x86`, `x64` and `aarch64`, and enabled on all other platforms.
- `XXH_FORCE_MEMORY_ACCESS`: The default method `0` uses a portable `memcpy()` notation.
Method `1` uses a gcc-specific `packed` attribute, which can provide better performance for some targets.
Method `2` forces unaligned reads, which is not standard compliant, but might sometimes be the only way to extract better read performance.
Method `3` uses a byteshift operation, which is best for old compilers which don't inline `memcpy()` or big-endian systems without a byteswap instruction.
- `XXH_CPU_LITTLE_ENDIAN`: By default, endianness is determined by a runtime test resolved at compile time.
If, for some reason, the compiler cannot simplify the runtime test, it can cost performance.
It's possible to skip auto-detection and simply state that the architecture is little-endian by setting this macro to 1.
Setting it to 0 states big-endian.
- `XXH_ENABLE_AUTOVECTORIZE`: Auto-vectorization may be triggered for XXH32 and XXH64, depending on cpu vector capabilities and compiler version.
Note: auto-vectorization tends to be triggered more easily with recent versions of `clang`.
For XXH32, SSE2 or equivalent (NEON) is enough, while XXH64 benefits from AVX512 but may also be vectorized with AVX2.
Unfortunately, auto-vectorization is generally detrimental to XXH performance.
For this reason, the xxhash source code tries to prevent auto-vectorization by default.
The loss can be severe: on a Zen5 cpu, with this option enabled,
XXH32 streaming is ~6x slower with `gcc` on baseline SSE2,
XXH64 streaming is ~3x slower with `clang` and AVX2,
and AVX512 vectorization is ~17% slower for both XXH32 and XXH64.
That being said, systems evolve, and this conclusion may change.
For example, it has been reported that recent Zen4 cpus are more likely to improve performance with vectorization.
Therefore, should you prefer or want to test vectorized code, you can enable this flag:
it will remove the no-vectorization protection code, thus making it more likely for XXH32 and XXH64 to be auto-vectorized.
- `XXH32_ENDJMP`: Switch multi-branch finalization stage of XXH32 by a single jump.
This is generally undesirable for performance, especially when hashing inputs of random sizes.
But depending on exact architecture and compiler, a jump might provide slightly better performance on small inputs. Disabled by default.
- `XXH_IMPORT`: MSVC specific: should only be defined for dynamic linking, as it prevents linkage errors.
- `XXH_NO_STDLIB`: Disable invocation of `<stdlib.h>` functions, notably `malloc()` and `free()`.
`libxxhash`'s `XXH*_createState()` will always fail and return `NULL`.
But one-shot hashing (like `XXH32()`) or streaming using statically allocated states
still work as expected.
This build flag is useful for embedded environments without dynamic allocation.
- `XXH_memcpy`, `XXH_memset`, `XXH_memcmp` : redirect `memcpy()`, `memset()` and `memcmp()` to some user-selected symbol at compile time.
Redirecting all 3 removes the need to include `<string.h>` standard library.
- `XXH_NO_EXTERNC_GUARD`: When `xxhash.h` is compiled in C++ mode, removes the `extern "C" { .. }` block guard.
- `XXH_DEBUGLEVEL` : When set to any value >= 1, enables `assert()` statements.
This (slightly) slows down execution, but may help finding bugs during debugging sessions.
### Binary size control
- `XXH_NO_XXH3` : removes symbols related to `XXH3` (both 64 & 128 bits) from generated binary.
`XXH3` is by far the largest contributor to `libxxhash` size,
so it's useful to reduce binary size for applications which do not employ `XXH3`.
- `XXH_NO_LONG_LONG`: removes compilation of algorithms relying on 64-bit `long long` types
which include `XXH3` and `XXH64`.
Only `XXH32` will be compiled.
Useful for targets (architectures and compilers) without 64-bit support.
- `XXH_NO_XXH32`: removes `XXH32` from generated binary.
Since `XXH3` depends on `XXH32`, it is removed too: only `XXH64` will be compiled.
- `XXH_NO_STREAM`: Disables the streaming API, limiting the library to single shot variants only.
- `XXH_NO_INLINE_HINTS`: By default, xxHash uses `__attribute__((always_inline))` and `__forceinline` to improve performance at the cost of code size.
Defining this macro to 1 will mark all internal functions as `static`, allowing the compiler to decide whether to inline a function or not.
This is very useful when optimizing for smallest binary size,
and is automatically defined when compiling with `-O0`, `-Os`, `-Oz`, or `-fno-inline` on GCC and Clang.
It may also be required to successfully compile using `-Og`, depending on compiler version.
- `XXH_SIZE_OPT`: `0`: default, optimize for speed
`1`: default for `-Os` and `-Oz`: disables some speed hacks for size optimization
`2`: makes code as small as possible, performance may cry
### Build modifiers specific to XXH3
- `XXH_VECTOR` : manually select a vector instruction set (default: auto-selected at compilation time). Available instruction sets are `XXH_SCALAR`, `XXH_SSE2`, `XXH_AVX2`, `XXH_AVX512`, `XXH_NEON` and `XXH_VSX`. Compiler may require additional flags to ensure proper support (for example, `gcc` on x86_64 requires `-mavx2` for `AVX2`, or `-mavx512f` for `AVX512`).
- `XXH_PREFETCH_DIST` : select prefetching distance. For close-to-metal adaptation to specific hardware platforms. XXH3 only.
- `XXH_NO_PREFETCH` : disable prefetching. Some platforms or situations may perform better without prefetching. XXH3 only.
### Build modifiers for the `xxhsum` CLI
- `XXH_1ST_SPEED_TARGET` : select an initial speed target, expressed in MiB/s, for the first speed test in benchmark mode. Benchmark will adjust the target at subsequent iterations, but the first test is made "blindly" by targeting this speed. Currently conservatively set to 10 MiB/s, to support very slow (emulated) platforms.
### Makefile variables
The following variables control runtime dispatch when building with `make`:
- `DISPATCH=1` : use `xxh_x86dispatch.c` in the Command Line Interface `xxhsum`, selecting at runtime between `scalar`, `sse2`, `avx2` or `avx512` instruction sets. This option is only valid for `x86`/`x64` systems. It is enabled by default when an `x86`/`x64` target is detected. It can be forcefully turned off using `DISPATCH=0`.
- `LIBXXH_DISPATCH=1` : enable the same runtime dispatch in both the static and dynamic `libxxhash` libraries. This option is only valid for `x86`/`x64` systems and is disabled by default. It is generally expected that library users will frequently hash short inputs, for which inlining is important and runtime dispatch may be detrimental, so this variable is disabled by default. It can nonetheless be explicitly selected. When enabled, the symbols declared in `xxh_x86dispatch.h` are included in the libraries and the header is installed. Applications must include this header to redirect the XXH3 entry points to their dispatched variants.
- `NODE_JS=1` : When compiling `xxhsum` for Node.js with Emscripten, this links the `NODERAWFS` library for unrestricted filesystem access and patches `isatty` to make the command line utility correctly detect the terminal. This does make the binary specific to Node.js.
License
-------
The library files `xxhash.c` and `xxhash.h`, and the source units in `lib/`,
are licensed under the [BSD 2-Clause License](LICENSE). The `xxhsum` command
line utility is licensed under [GPLv2](cli/COPYING).
Other programming languages
---------------------------
Beyond the C reference version,
xxHash is also available from many different programming languages,
thanks to great contributors.
They are [listed on the xxHash website](https://xxhash.com/#other-languages).
Special thanks
--------------
- Takayuki Matsuoka, aka @t-mat, for creating `xxhsum -c` and great support during early xxh releases
- Mathias Westerdahl, aka @JCash, for introducing the first version of `XXH64`
- Devin Hussey, aka @easyaspi314, for incredible low-level optimizations on `XXH3` and `XXH128`